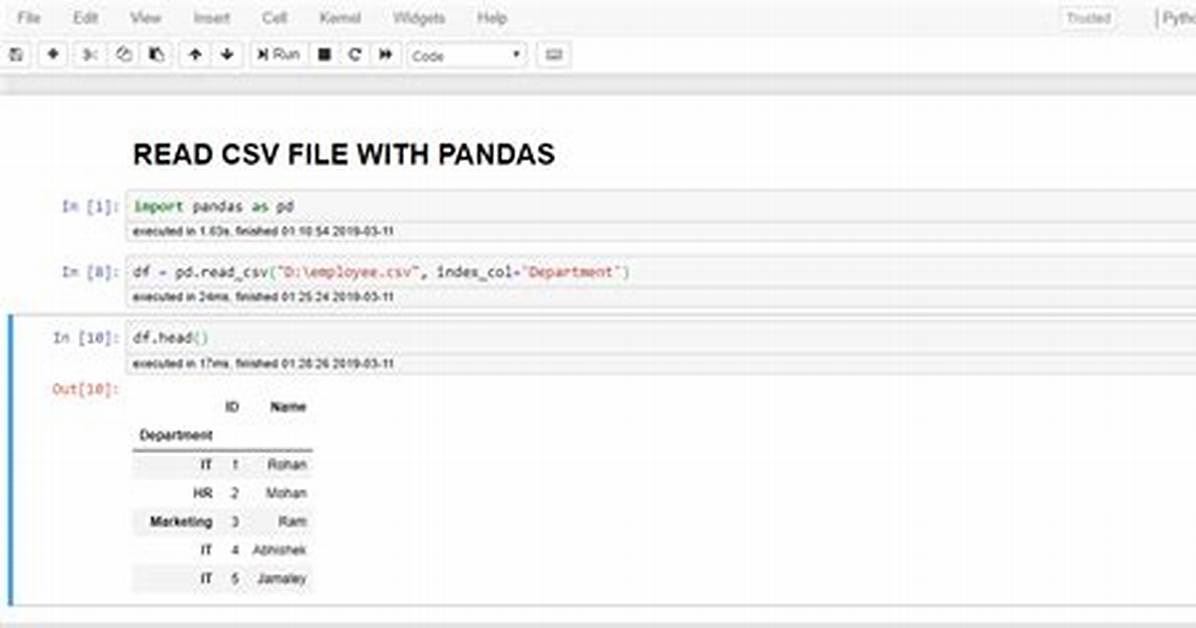
I'm attempting to read a CSV file into a Dataframe in Pandas. When I try to do that, I get the following error:
UnicodeDecodeError: 'utf-8' codec can't decode byte 0x96 in position 55: invalid start byte
This is from code:
import pandas as pd

location = r"C:\Users\khtad\Documents\test.csv"

df = pd.read_csv(location, header=0, quotechar='"')
This is on a Windows 7 Enterprise Service Pack 1 machine and it seems to apply to every CSV file I create. In this particular case the binary from location 55 is 00101001 and location 54 is 01110011, if that matters.
Saving the file as UTF-8 with a text editor doesn't seem to help, either. Similarly, adding the param "encoding='utf-8' doesn't work, either--it returns the same error.
What is the most likely cause of this error and are there any workarounds other than abandoning the DataFrame construct for the moment and using the csv module to read in the CSV line-by-line?
2 Answers
Try calling read_csv with encoding='latin1', encoding='iso-8859-1' or encoding='cp1252' (these are some of the various encodings found on Windows).
This works in Mac as well you can use
df= pd.read_csv('Region_count.csv', encoding ='latin1')

