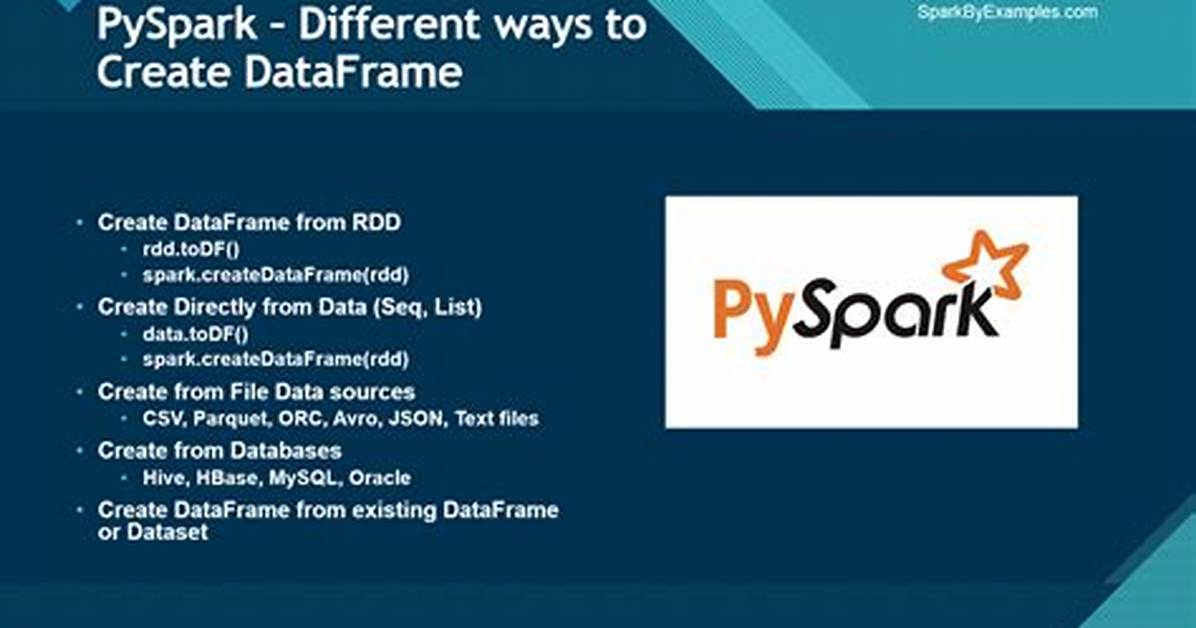
I am trying to manually create a pyspark dataframe given certain data:
row_in = [(1566429545575348), (40.353977), (-111.701859)]
rdd = sc.parallelize(row_in)
schema = StructType(
    [
        StructField("time_epocs", DecimalType(), True),
        StructField("lat", DecimalType(), True),
        StructField("long", DecimalType(), True),
    ]
)
df_in_test = spark.createDataFrame(rdd, schema)
This gives an error when I try to display the dataframe, so I am not sure how to do this.
However, the Spark documentation seems to be a bit convoluted to me, and I got similar errors when I tried to follow those instructions.
Does anyone know how to do this?
6 Answers
Simple dataframe creation:
df = spark.createDataFrame(
    [
        (1, "foo"),  # create your data here, be consistent in the types.
        (2, "bar"),
    ],
    ["id", "label"]  # add your column names here
)

df.printSchema()
root
 |-- id: long (nullable = true)
 |-- label: string (nullable = true)

df.show()
+---+-----+
| id|label|
+---+-----+
|  1|  foo|
|  2|  bar|
+---+-----+
According to official doc:
- when schema is a list of column names, the type of each column will be inferred from data. (example above ↑)
- When schema is
pyspark.sql.types.DataTypeor a datatype string, it must match the real data. (examples below ↓)
# Example with a datatype string
df = spark.createDataFrame(
    [
        (1, "foo"),  # Add your data here
        (2, "bar"),
    ],
    "id int, label string",  # add column names and types here
)

# Example with pyspark.sql.types
from pyspark.sql import types as T
df = spark.createDataFrame(
    [
        (1, "foo"),  # Add your data here
        (2, "bar"),
    ],
    T.StructType(  # Define the whole schema within a StructType
        [
            T.StructField("id", T.IntegerType(), True),
            T.StructField("label", T.StringType(), True),
        ]
    ),
)


df.printSchema()
root
 |-- id: integer (nullable = true)  # type is forced to Int
 |-- label: string (nullable = true)
Additionally, you can create your dataframe from Pandas dataframe, schema will be inferred from Pandas dataframe's types :
import pandas as pd
import numpy as np


pdf = pd.DataFrame(
    {
        "col1": [np.random.randint(10) for x in range(10)],
        "col2": [np.random.randint(100) for x in range(10)],
    }
)


df = spark.createDataFrame(pdf)

df.show()
+----+----+
|col1|col2|
+----+----+
|   6|   4|
|   1|  39|
|   7|   4|
|   7|  95|
|   6|   3|
|   7|  28|
|   2|  26|
|   0|   4|
|   4|  32|
+----+----+
To elaborate/build off of @Steven's answer:
field = [
    StructField("MULTIPLIER", FloatType(), True),
    StructField("DESCRIPTION", StringType(), True),
]
schema = StructType(field)
multiplier_df = sqlContext.createDataFrame(sc.emptyRDD(), schema)
Will create a blank dataframe.
We can now simply add a row to it:
l = [(2.3, "this is a sample description")]
rdd = sc.parallelize(l)
multiplier_df_temp = spark.createDataFrame(rdd, schema)
multiplier_df = wtp_multiplier_df.union(wtp_multiplier_df_temp)
This answer demonstrates how to create a PySpark DataFrame with createDataFrame, create_df and toDF.
df = spark.createDataFrame([("joe", 34), ("luisa", 22)], ["first_name", "age"])

df.show()
+----------+---+
|first_name|age|
+----------+---+
|       joe| 34|
|     luisa| 22|
+----------+---+
You can also pass createDataFrame a RDD and schema to construct DataFrames with more precision:
from pyspark.sql import Row
from pyspark.sql.types import *

rdd = spark.sparkContext.parallelize([
    Row(name='Allie', age=2),
    Row(name='Sara', age=33),
    Row(name='Grace', age=31)])

schema = schema = StructType([
   StructField("name", StringType(), True),
   StructField("age", IntegerType(), False)])

df = spark.createDataFrame(rdd, schema)

df.show()
+-----+---+
| name|age|
+-----+---+
|Allie|  2|
| Sara| 33|
|Grace| 31|
+-----+---+
create_df from my Quinn project allows for the best of both worlds - it's concise and fully descriptive:
from pyspark.sql.types import *
from quinn.extensions import *

df = spark.create_df(
    [("jose", "a"), ("li", "b"), ("sam", "c")],
    [("name", StringType(), True), ("blah", StringType(), True)]
)

df.show()
+----+----+
|name|blah|
+----+----+
|jose|   a|
|  li|   b|
| sam|   c|
+----+----+
toDF doesn't offer any advantages over the other approaches:
from pyspark.sql import Row

rdd = spark.sparkContext.parallelize([
    Row(name='Allie', age=2),
    Row(name='Sara', age=33),
    Row(name='Grace', age=31)])
df = rdd.toDF()
df.show()
+-----+---+
| name|age|
+-----+---+
|Allie|  2|
| Sara| 33|
|Grace| 31|
+-----+---+
With formatting
from pyspark.sql import SparkSession
from pyspark.sql.types import StructField, StructType, IntegerType, StringType

spark = SparkSession.builder.getOrCreate()
df = spark.createDataFrame(
    [
        (1, "foo"),
        (2, "bar"),
    ],
    StructType(
        [
            StructField("id", IntegerType(), False),
            StructField("txt", StringType(), False),
        ]
    ),
)
print(df.dtypes)
df.show()
Extending @Steven's Answer:
data = [(i, 'foo') for i in range(1000)] # random data

columns = ['id', 'txt']    # add your columns label here

df = spark.createDataFrame(data, columns)
Note: When schema is a list of column-names, the type of each column will be inferred from data.
If you want to specifically define schema then do this:
from pyspark.sql.types import StructType, StructField, IntegerType, StringType
schema = StructType([StructField("id", IntegerType(), True), StructField("txt", StringType(), True)])
df1 = spark.createDataFrame(data, schema)
Outputs:
>>> df1
DataFrame[id: int, txt: string]
>>> df
DataFrame[id: bigint, txt: string]
for beginners, a full example importing data from file:
from pyspark.sql import SparkSession
from pyspark.sql.types import (
    ShortType,
    StringType,
    StructType,
    StructField,
    TimestampType,
)

import os

here = os.path.abspath(os.path.dirname(__file__))


spark = SparkSession.builder.getOrCreate()
schema = StructType(
    [
        StructField("id", ShortType(), nullable=False),
        StructField("string", StringType(), nullable=False),
        StructField("datetime", TimestampType(), nullable=False),
    ]
)

# read file or construct rows manually
df = spark.read.csv(os.path.join(here, "data.csv"), schema=schema, header=True)

