I built an xarray dataset in python3 with coordinates (time, levels) to identify all cloud bases and cloud tops during one day of observations. The variable levels is the dimension for the cloud base/tops that can be identified at a given time. It stores cloud base/top heights values for each time.
Now I want to select all the cloud bases and tops that are located within a given range of heights that change in time. The height range is identified by the arrays bottom_mod and top_mod. These arrays have a time dimension and contain the edges of the range of heights to be selected.
The xarray dataset is cloudStandard_mod_reshaped:
Dimensions:     (levels: 8, time: 9600)
Coordinates:
  * levels      (levels) int64 0 1 2 3 4 5 6 7
  * time        (time) datetime64[ns] 2013-04-14 ... 2013-04-14T23:59:51
Data variables:
    cloudTop    (time, levels) float64 nan nan nan nan nan ... nan nan nan nan
    cloudThick  (time, levels) float64 nan nan nan nan nan ... nan nan nan nan
    cloudBase   (time, levels) float64 nan nan nan nan nan ... nan nan nan nan
I tried to select the heights in the range identified by top and bottom array as follows:
PBLclouds = cloudStandard_mod_reshaped.sel(levels=slice(bottom_mod[:], top_mod[:]))
but this instruction does accept only scalar values for the slice command.
Do you know how to slice with values that are coordinate-dependent?
1 Answer
You can use the .where() method.
The line providing the solution is under 2.
1. First, create some data like yours:
The dataset:
nlevels, ntime = 8, 50

ds = xr.Dataset(
    coords=dict(levels=np.arange(nlevels), time=np.arange(ntime),),
    data_vars=dict(
        cloudTop=(("levels", "time"), np.random.randn(nlevels, ntime)),
        cloudThick=(("levels", "time"), np.random.randn(nlevels, ntime)),
        cloudBase=(("levels", "time"), np.random.randn(nlevels, ntime)),
    ),
)
output of print(ds):
<xarray.Dataset>
Dimensions:     (levels: 8, time: 50)
Coordinates:
  * levels      (levels) int64 0 1 2 3 4 5 6 7
  * time        (time) int64 0 1 2 3 4 5 6 7 8 9 ... 41 42 43 44 45 46 47 48 49
Data variables:
    cloudTop    (levels, time) float64 0.08375 0.04721 0.9379 ... 0.04877 2.339
    cloudThick  (levels, time) float64 -0.6441 -0.8338 -1.586 ... -1.026 -0.5652
    cloudBase   (levels, time) float64 -0.05004 -0.1729 0.7154 ... 0.06507 1.601
For the top and bottom levels, I'll make the bottom level random and just add an offset to construct the top level.
offset = 3

bot_mod = xr.DataArray(
    dims=("time"),
    coords=dict(time=np.arange(ntime)),
    data=np.random.randint(0, nlevels - offset, ntime),
    name="bot_mod",
)

top_mod = (bot_mod + offset).rename("top_mod")
output of print(bot_mod):
<xarray.DataArray 'bot_mod' (time: 50)>
array([0, 1, 2, 2, 3, 1, 2, 1, 0, 2, 1, 3, 2, 0, 2, 4, 3, 3, 2, 1, 2, 0,
       2, 2, 0, 1, 1, 4, 1, 3, 0, 4, 0, 4, 4, 0, 4, 4, 1, 0, 3, 4, 4, 3,
       3, 0, 1, 2, 4, 0])
2. Then, select the range of levels where clouds are:
use .where() method to select the dataset variables that are between the bottom level and the top level:
ds_clouds = ds.where((ds.levels > bot_mod) & (ds.levels < top_mod))
output of print(ds_clouds):
<xarray.Dataset>
Dimensions:     (levels: 8, time: 50)
Coordinates:
  * levels      (levels) int64 0 1 2 3 4 5 6 7
  * time        (time) int64 0 1 2 3 4 5 6 7 8 9 ... 41 42 43 44 45 46 47 48 49
Data variables:
    cloudTop    (levels, time) float64 nan nan nan nan nan ... nan nan nan nan
    cloudThick  (levels, time) float64 nan nan nan nan nan ... nan nan nan nan
    cloudBase   (levels, time) float64 nan nan nan nan nan ... nan nan nan nan
It puts nan where the condition is not satisfied, you can use the .dropna() method to get rid of those.
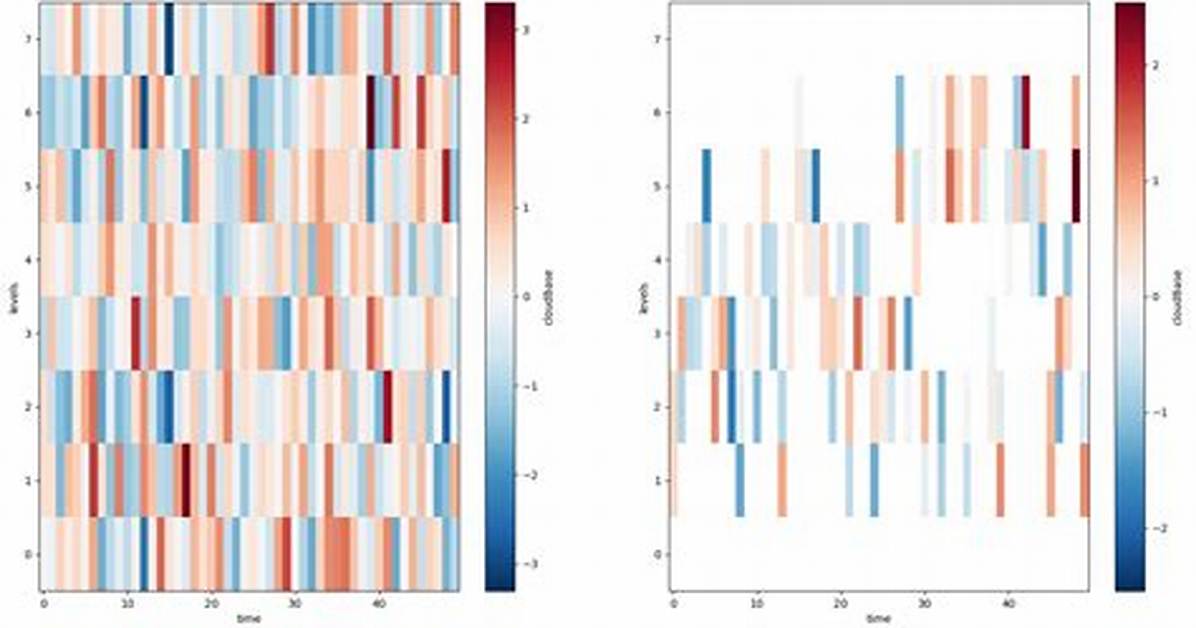
3. Check for success:
Plot cloudBase variable of the dataset before and after processing:
fig, axes = plt.subplots(ncols=2)

ds.cloudBase.plot.imshow(ax=axes[0])
ds_clouds.cloudBase.plot.imshow(ax=axes[1])

plt.show()
I'm not yet allowed to embed images, so that's a link:

