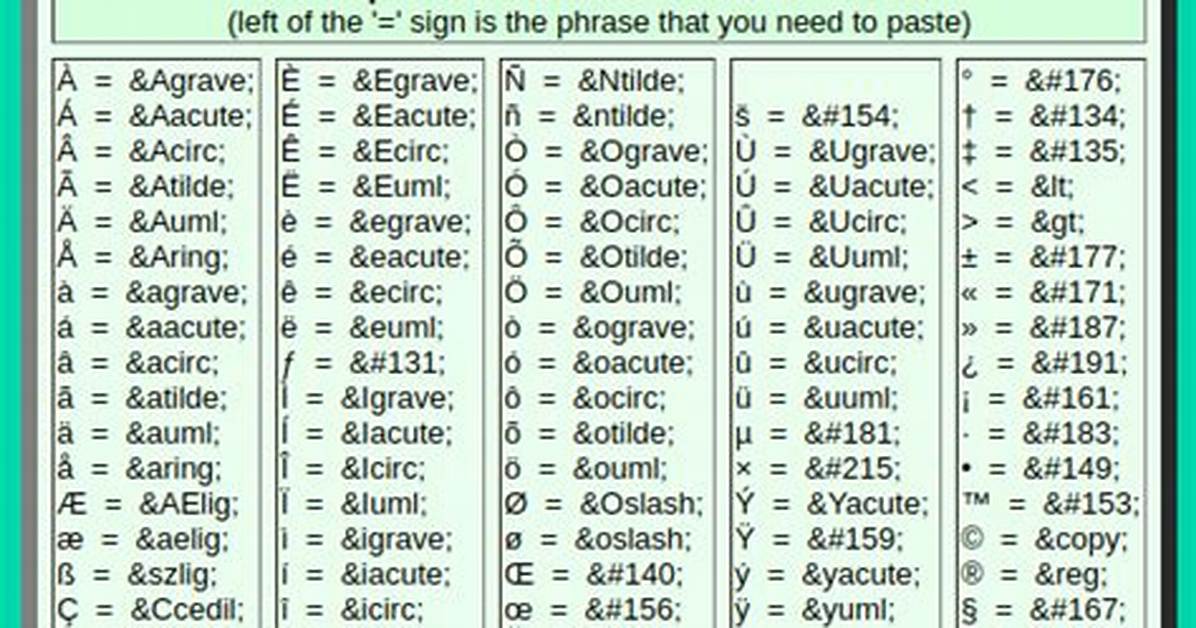
How can I convert special characters to HTML in JavaScript?
Example:
&(ampersand) becomes&."(double quote) becomes"whenENT_NOQUOTESis not set.'(single quote) becomes'only whenENT_QUOTESis set.<(less than) becomes<.>(greater than) becomes>.
25 Answers
The best way in my opinion is to use the browser's inbuilt HTML escape functionality to handle many of the cases. To do this simply create a element in the DOM tree and set the innerText of the element to your string. Then retrieve the innerHTML of the element. The browser will return an HTML encoded string.
function HtmlEncode(s)
{
  var el = document.createElement("div");
  el.innerText = el.textContent = s;
  s = el.innerHTML;
  return s;
}
Test run:
alert(HtmlEncode('&;\'><"'));
Output:
&;'><"
This method of escaping HTML is also used by the Prototype JS library though differently from the simplistic sample I have given.
Note: You will still need to escape quotes (double and single) yourself. You can use any of the methods outlined by others here.
You need a function that does something like
return mystring.replace(/&/g, "&").replace(/>/g, ">").replace(/</g, "<").replace(/"/g, """);
But taking into account your desire for different handling of single/double quotes.
For those who want to decode an integer char code like &#xxx; inside a string, use this function:
function decodeHtmlCharCodes(str) {
  return str.replace(/(&#(\d+);)/g, function(match, capture, charCode) {
    return String.fromCharCode(charCode);
  });
}

// Will output "The show that gained int’l reputation’!"
console.log(decodeHtmlCharCodes('The show that gained int’l reputation’!'));
ES6
const decodeHtmlCharCodes = str =>
  str.replace(/(&#(\d+);)/g, (match, capture, charCode) =>
    String.fromCharCode(charCode));

// Will output "The show that gained int’l reputation’!"
console.log(decodeHtmlCharCodes('The show that gained int’l reputation’!'));This generic function encodes every nonalphabetic character to its HTML code (numeric character reference (NCR)):
function HTMLEncode(str) {
    var i = str.length,
        aRet = [];

    while (i--) {
        var iC = str[i].charCodeAt();
        if (iC < 65 || iC > 127 || (iC>90 && iC<97)) {
            aRet[i] = '&#'+iC+';';
        } else {
            aRet[i] = str[i];
        }
    }
    return aRet.join('');
}
[edit 2022] More modern approach:
const toHtmlEntities = (str, showInHtml = false) =>
  [...str].map( v => `${showInHtml ? `&#` : `&#`}${v.charCodeAt(0)};`).join(``);
const str = `&Hellõ Wórld`;

document.body.insertAdjacentHTML(`beforeend`, `<ul>
  <li>Show the entities (<code>toHtmlEntities(str, true)</code>): <b>${
    toHtmlEntities(str, true)}</b></li>
  <li>Let the browser decide (<code>toHtmlEntities(str)</code>): <b>${
    toHtmlEntities(str)}</b></li>
  <li id="textOnly"></li></ul>`);
document.querySelector(`#textOnly`).textContent = `As textContent: ${
  toHtmlEntities(str)}`;
body {
font: 14px / 18px "normal verdana", arial;
margin: 1rem;
}
code {
background-color: #eee;
}Create a function that uses string replace
function convert(str)
{
str = str.replace(/&/g, "&");
str = str.replace(/>/g, ">");
str = str.replace(/</g, "<");
str = str.replace(/"/g, """);
str = str.replace(/'/g, "'");
return str;
}
From Mozilla ...
Note that charCodeAt will always return a value that is less than 65,536. This is because the higher code points are represented by a pair of (lower valued) "surrogate" pseudo-characters which are used to comprise the real character. Because of this, in order to examine or reproduce the full character for individual characters of value 65,536 and above, for such characters, it is necessary to retrieve not only charCodeAt(i), but also charCodeAt(i+1) (as if examining/reproducing a string with two >letters).
The Best Solution
/**
 * (c) 2012 Steven Levithan <
 * MIT license
 */
if (!String.prototype.codePointAt) {
    String.prototype.codePointAt = function (pos) {
        pos = isNaN(pos) ? 0 : pos;
        var str = String(this),
            code = str.charCodeAt(pos),
            next = str.charCodeAt(pos + 1);
        // If a surrogate pair
        if (0xD800 <= code && code <= 0xDBFF && 0xDC00 <= next && next <= 0xDFFF) {
            return ((code - 0xD800) * 0x400) + (next - 0xDC00) + 0x10000;
        }
        return code;
    };
}

/**
 * Encodes special html characters
 * @param string
 * @return {*}
 */
function html_encode(string) {
    var ret_val = '';
    for (var i = 0; i < string.length; i++) {
        if (string.codePointAt(i) > 127) {
            ret_val += '&#' + string.codePointAt(i) + ';';
        } else {
            ret_val += string.charAt(i);
        }
    }
    return ret_val;
}
Usage example:
html_encode("✈");
As was mentioned by dragon the cleanest way to do it is with jQuery:
function htmlEncode(s) {
    return $('<div>').text(s).html();
}

function htmlDecode(s) {
    return $('<div>').html(s).text();
}
function char_convert() {
var chars = ["©","Û","®","ž","Ü","Ÿ","Ý","$","Þ","%","¡","ß","¢","à","£","á","À","¤","â","Á","¥","ã","Â","¦","ä","Ã","§","å","Ä","¨","æ","Å","©","ç","Æ","ª","è","Ç","«","é","È","¬","ê","É","","ë","Ê","®","ì","Ë","¯","í","Ì","°","î","Í","±","ï","Î","²","ð","Ï","³","ñ","Ð","´","ò","Ñ","µ","ó","Õ","¶","ô","Ö","·","õ","Ø","¸","ö","Ù","¹","÷","Ú","º","ø","Û","»","ù","Ü","@","¼","ú","Ý","½","û","Þ","€","¾","ü","ß","¿","ý","à","‚","À","þ","á","ƒ","Á","ÿ","å","„","Â","æ","…","Ã","ç","†","Ä","è","‡","Å","é","ˆ","Æ","ê","‰","Ç","ë","Š","È","ì","‹","É","í","Œ","Ê","î","Ë","ï","Ž","Ì","ð","Í","ñ","Î","ò","‘","Ï","ó","’","Ð","ô","“","Ñ","õ","”","Ò","ö","•","Ó","ø","–","Ô","ù","—","Õ","ú","˜","Ö","û","™","×","ý","š","Ø","þ","›","Ù","ÿ","œ","Ú"];
var codes = ["©","Û","®","ž","Ü","Ÿ","Ý","$","Þ","%","¡","ß","¢","à","£","á","À","¤","â","Á","¥","ã","Â","¦","ä","Ã","§","å","Ä","¨","æ","Å","©","ç","Æ","ª","è","Ç","«","é","È","¬","ê","É","­","ë","Ê","®","ì","Ë","¯","í","Ì","°","î","Í","±","ï","Î","²","ð","Ï","³","ñ","Ð","´","ò","Ñ","µ","ó","Õ","¶","ô","Ö","·","õ","Ø","¸","ö","Ù","¹","÷","Ú","º","ø","Û","»","ù","Ü","@","¼","ú","Ý","½","û","Þ","€","¾","ü","ß","¿","ý","à","‚","À","þ","á","ƒ","Á","ÿ","å","„","Â","æ","…","Ã","ç","†","Ä","è","‡","Å","é","ˆ","Æ","ê","‰","Ç","ë","Š","È","ì","‹","É","í","Œ","Ê","î","Ë","ï","Ž","Ì","ð","Í","ñ","Î","ò","‘","Ï","ó","’","Ð","ô","“","Ñ","õ","”","Ò","ö","•","Ó","ø","–","Ô","ù","—","Õ","ú","˜","Ö","û","™","×","ý","š","Ø","þ","›","Ù","ÿ","œ","Ú"];
for(x=0; x<chars.length; x++){
for (i=0; i<arguments.length; i++){
arguments[i].value = arguments[i].value.replace(chars[x], codes[x]);
}
}
}
char_convert(this);
function ConvChar(str) {
c = {'<':'&lt;', '>':'&gt;', '&':'&amp;',
'"':'&quot;', "'":'&#039;', '#':'&#035;' };
return str.replace(/[<&>'"#]/g, function(s) { return c[s]; });
}
alert(ConvChar('<-"-&-"->-<-\'-#-\'->'));
Result:
<-"-&amp;-"->-<-'-#-'->
In a testarea tag:
<-"-&-"->-<-'-#-'->
If you'll just change a few characters in long code...
If you need support for all standardized named character references, Unicode and ambiguous ampersands, the he library is the only 100% reliable solution I'm aware of!
Example use
he.encode('foo © bar ≠ baz 𝌆 qux');
// Output: 'foo © bar ≠ baz 𝌆 qux'

he.decode('foo © bar ≠ baz 𝌆 qux');
// Output: 'foo © bar ≠ baz 𝌆 qux'
In a PRE tag - and in most other HTML tags - plain text for a batch file that uses the output redirection characters (< and >) will break the HTML, but here is my tip: anything goes in a TEXTAREA element - it will not break the HTML, mainly because we are inside a control instanced and handled by the OS, and therefore its content are not being parsed by the HTML engine.
As an example, say I want to highlight the syntax of my batch file using JavaScript. I simply paste the code in a textarea without worrying about the HTML reserved characters, and have the script process the innerHTML property of the textarea, which evaluates to the text with the HTML reserved characters replaced by their corresponding ISO 8859-1 entities.
Browsers will escape special characters automatically when you retrieve the innerHTML (and outerHTML) property of an element. Using a textarea (and who knows, maybe an input of type text) just saves you from doing the conversion (manually or through code).
I use this trick to test my syntax highlighter, and when I'm done authoring and testing, I simply hide the textarea from view.
A workaround:
var temp = $("div").text("<");
var afterEscape = temp.html(); // afterEscape == "<"
Here's a good library I've found very useful in this context.
According to its author:
It supports all standardized named character references as per HTML, handles ambiguous ampersands and other edge cases just like a browser would, has an extensive test suite, and — contrary to many other JavaScript solutions — he handles astral Unicode symbols just fine
Use:
var swapCodes   = new Array(8211, 8212, 8216, 8217, 8220, 8221, 8226, 8230, 8482, 169, 61558, 8226, 61607);
var swapStrings = new Array("--", "--", "'",  "'",  '"',  '"',  "*",  "...", "™", "©", "•", "•", "•");

var TextCheck = {
    doCWBind:function(div){
        $(div).bind({
            bind:function(){
                TextCheck.cleanWord(div);
            },
            focus:function(){
                TextCheck.cleanWord(div);
            },
            paste:function(){
                TextCheck.cleanWord(div);
            }
        });
    },
    cleanWord:function(div){
        var output = $(div).val();
        for (i = 0; i < swapCodes.length; i++) {
            var swapper = new RegExp("\\u" + swapCodes[i].toString(16), "g");
            output = output.replace(swapper, swapStrings[i]);
        }
        $(div).val(output);
    }
}
Another one that we use now that works. The one above I have it calling a script instead and returns the converted code. It is only good on small textareas (meaning not a full on article, blog, etc.)
For the above. It works on most characters.
var swapCodes   = new Array(8211, 8212, 8216, 8217, 8220, 8221, 8226, 8230, 8482, 61558, 8226, 61607, 161, 162, 163, 164, 165, 166, 167, 168, 169, 170, 171, 172, 173, 174, 175, 176, 177, 178, 179, 180, 181, 182, 183, 184, 185, 186, 187, 188, 189, 190, 191, 192, 193, 194, 195, 196, 197, 198, 199, 200, 201, 202, 203, 204, 205, 206, 207, 208, 209, 210, 211, 212, 213, 214, 215, 216, 217, 218, 219, 220, 221, 222, 223, 224, 225, 226, 227, 228, 229, 230, 231, 232, 233, 234, 235, 236, 237, 238, 239, 240, 241, 242, 243, 244, 245, 246, 247, 248, 249, 250, 251, 252, 253, 254, 255, 338, 339, 352, 353, 376, 402);
var swapStrings = new Array("--", "--", "'",  "'",  '"',  '"',  "*",  "...", "™", "•", "•", "•", "¡", "¢", "£", "¤", "¥", "¦", "§", "¨", "©", "ª", "«", "¬", "­", "®", "¯", "°", "±", "²", "³", "´", "µ", "¶", "·", "¸", "¹", "º", "»", "¼", "½", "¾", "¿", "À", "Á", "Â", "Ã", "Ä", "Å", "Æ", "Ç", "È", "É", "Ê", "Ë", "Ì", "Í", "Î", "Ï", "Ð", "Ñ", "Ò", "Ó", "Ô", "Õ", "Ö", "×", "Ø", "Ù", "Ú", "Û", "Ü", "Ý", "Þ", "ß", "à", "á", "â", "ã", "ä", "å", "æ", "ç", "è", "é", "ê", "ë", "ì", "í", "î", "ï", "ð", "ñ", "ò", "ó", "ô", "õ", "ö", "÷", "ø", "ù", "ú", "û", "ü", "ý", "þ", "ÿ", "Œ", "œ", "Š", "š", "Ÿ", "ƒ");
I create a javascript file that has a lot of functionality including the above.
All files needed are included. I added jQuery 1.4.4. Simply because I saw issues in other versions, yet to try them out.
Requires: jQuery & jQuery Impromptu from:

1. Word Count
2. Character Conversion
3. Checks to ensure this is not passed: "notsomeverylongstringmissingspaces"
4. Checks to make sure ALL IS NOT ALL UPPERCASE.
5. Strip HTML

    // Word Counter
    $.getScript('js/characters.js', function(){
        $('#adtxt').bind("keyup click blur focus change paste",
            function(event){
                TextCheck.wordCount(30, "#adtxt", "#adtxt_count", event);
        });
        $('#adtxt').blur(
            function(event){
                TextCheck.check_length('#adtxt'); // unsures properly spaces-not one long word
                TextCheck.doCWBind('#adtxt'); // char conversion
        });

        TextCheck.wordCount(30, "#adtxt", "#adtxt_count", false);
    });

    //HTML
    <textarea name="adtxt" id="adtxt" rows="10" cols="70" class="wordCount"></textarea>

    <div id="adtxt_count" class="clear"></div>

    // Just Character Conversions:
    TextCheck.doCWBind('#myfield');

    // Run through form fields in a form for case checking.
    // Alerts user when field is blur'd.
    var labels = new Array("Brief Description", "Website URL", "Contact Name", "Website", "Email", "Linkback URL");
    var checking = new Array("descr", "title", "fname", "website", "email", "linkback");
    TextCheck.check_it(checking, labels);

    // Extra security to check again, make sure form is not submitted
    var pass = TextCheck.validate(checking, labels);
    if(pass){
        // Do form actions
    }

    //Strip HTML
    <textarea name="adtxt" id="adtxt" rows="10" cols="70" onblur="TextCheck.stripHTML(this);"></textarea>
<!doctype html>
<html lang="en">
<head>
<meta charset="utf-8">
<title>html</title>
<script>
$(function() {
document.getElementById('test').innerHTML = "&";
});
</script>
</head>
<body>
<div id="test"></div>
</body>
</html>
You can simply convert special characters to HTML using the above code.
function escape (text)
{
  return text.replace(/[<>\&\"\']/g, function(c) {
    return '&#' + c.charCodeAt(0) + ';';
  });
}

alert(escape("<>&'\""));
This doesn't direcly answer your question, but if you are using innerHTML in order to write text within an element and you ran into encoding issues, just use textContent, i.e.:
var s = "Foo 'bar' baz <qux>";

var element = document.getElementById('foo');
element.textContent = s;

// <div id="foo">Foo 'bar' baz <qux></div>
Here are a couple methods I use without the need of jQuery:
You can encode every character in your string:
function encode(e){return e.replace(/[^]/g, function(e) {return "&#" + e.charCodeAt(0) + ";"})}
Or just target the main safe encoding characters to worry about (&, inebreaks, <, >, " and ') like:
function encode(r){
return r.replace(/[\x26\x0A\<>'"]/g, function(r){return "&#" + r.charCodeAt(0) + ";"})
}
test.value = encode('How to encode\nonly html tags &<>\'" nice & fast!');
/*************
* \x26 is &ersand (it has to be first),
* \x0A is newline,
*************/<textarea id=test rows="9" cols="55">We can use JavaScript's DOMParser for special characters conversion.
const parser = new DOMParser();
const convertedValue = (parser.parseFromString("' & ' < >", "application/xml").body.innerText;
If you're using Lodash, you can do (copy pasted from documentation):
_.escape('fred, barney, & pebbles');
// => 'fred, barney, & pebbles'
For more information: _.escape([string=''])
I had struggled with this myself for quite some time, but I settled on using this negative match regex to match all special characters and convert them to their relevant character codes:
var encoded = value.replace(/[^A-Za-z0-9]/g, function(i) {
    return '&#' + i.charCodeAt(0) + ';';
});
Yes, but if you need to insert the resulting string somewhere without it being converted back, you need to do:
str.replace(/'/g,"&amp;#39;"); // and so on
<html>
<body>
<script type="text/javascript">
var str = "&\"'<>";
alert('B4 Change: \n' + str);
str = str.replace(/\&/g, '&');
str = str.replace(/</g, '<');
str = str.replace(/>/g, '>');
str = str.replace(/\"/g, '"');
str = str.replace(/\'/g, ''');
alert('After change: \n' + str);
</script>
</body>
</html>
Use this to test:
The following is the a function to encode XML escaped characters in JavaScript:
Encoder.htmlEncode(unsafeText);

