So I wish to create a process using the python multiprocessing module, I want it be part of a larger script. (I also want a lot of other things from it but right now I will settle for this)
I copied the most basic code from the multiprocessing docs and modified it slightly
However, everything outside of the if __name__ == '__main__': statement gets repeated every time p.join() is called.
This is my code:
from multiprocessing import Process

data = 'The Data'
print(data)

# worker function definition
def f(p_num):
    print('Doing Process: {}'.format(p_num))

print('start of name == main ')

if __name__ == '__main__':
    print('Creating process')
    p = Process(target=f, args=(data,))
    print('Process made')
    p.start()
    print('process started')
    p.join()
    print('process joined')

print('script finished')
This is what I expected:
The Data
start of name == main
Creating process
Process made
process started
Doing Process: The Data
process joined
script finished

Process finished with exit code 0
This is the reality:
The Data
start of name == main
Creating process
Process made
process started
The Data                         <- wrongly repeated line
start of name == main            <- wrongly repeated line
script finished                  <- wrongly executed early line
Doing Process: The Data
process joined
script finished

Process finished with exit code 0
I am not sure whether this is caused by the if statement or p.join() or something else and by extension why this is happening. Can some one please explain what caused this and why?
For clarity because some people cannot replicate my problem but I have; I am using Windows Server 2012 R2 Datacenter and I am using python 3.5.3.
2 Answers
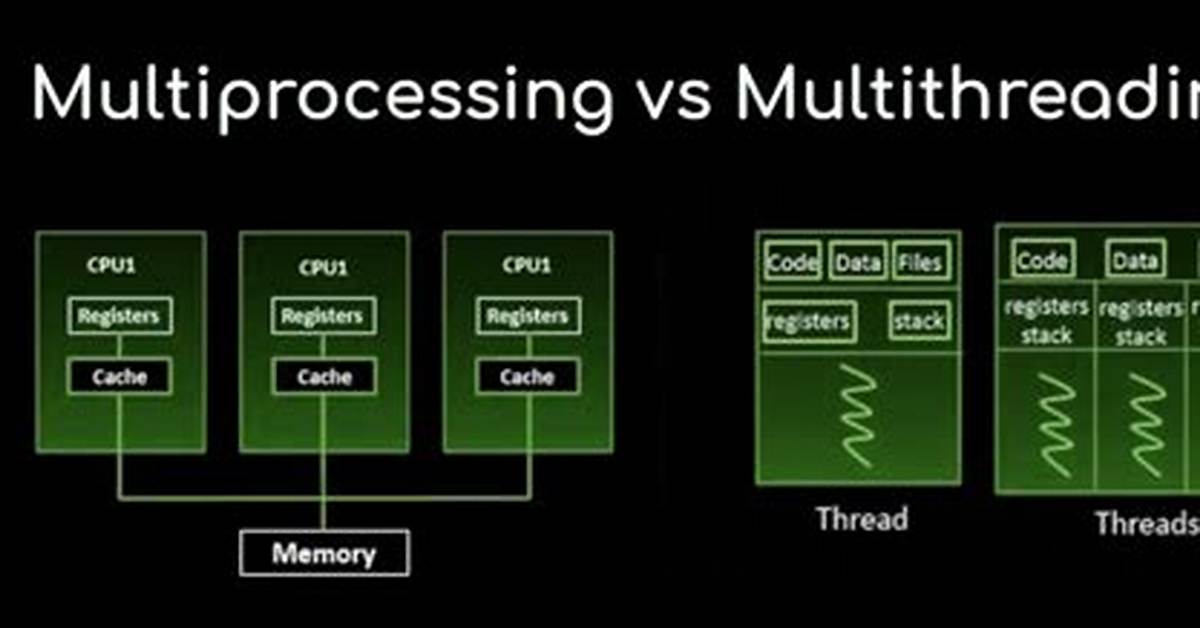
The way Multiprocessing works in Python is such that each child process imports the parent script. In Python, when you import a script, everything not defined within a function is executed. As I understand it, __name__ is changed on an import of the script (Check this SO answer here for a better understanding), which is different than if you ran the script on the command line directly, which would result in __name__ == '__main__'. This import results in __name__ not equalling '__main__', which is why the code in if __name__ == '__main__': is not executed for your subprocess.
Anything you don't want executed during subprocess calls should be moved into your if __name__ == '__main__': section of your code, as this will only run for the parent process, i.e. the script you run initially.
Hope this helps a bit. There are some more resources around Google that better explain this if you look around. I linked the official Python resource for the multiprocessing module, and I recommend you look through it.
Exploring the topic I run into an issue of multiple loads of modules. to make it work per above I had to:
- put all imports in a function (initializer())
- return all imports as objects in the call to initializer() function
- reference those objects in definition and calls to the remaining functions in my module
the example module below runs multiple classification approaches on the same dataset in parallel:
print("I am being run so often because: ")

def initializer():
    from sklearn import datasets

    iris = datasets.load_iris()
    x = iris.data
    y = iris.target

    from sklearn.preprocessing import StandardScaler as StandardScaler
    from sklearn.metrics import accuracy_score
    from sklearn.linear_model import Perceptron
    from sklearn.linear_model import LogisticRegression
    from sklearn.pipeline import Pipeline
    import multiprocessing as mp
    from multiprocessing import Manager

    results = [] # for some reason it needs to be defined before the if __name__ = __main__

    return x, y, StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline, mp, Manager, results

def perceptron(x,y,results, StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline):
    scaler = StandardScaler()
    estimator = ["Perceptron", Perceptron(n_iter=40, eta0=0.1, random_state=1)]

    pipe =  Pipeline([('Scaler', scaler),
                      ('Estimator', estimator[1])])

    pipe.fit(x,y)

    y_pred_pipe = pipe.predict(x)
    accuracy = accuracy_score(y, y_pred_pipe)
    result = [estimator[0], estimator[1], pipe, y_pred_pipe, accuracy]
    results.append(result)
    print(estimator[0], "Accuracy: ",accuracy)
    return results

def logistic(x,y,results,StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline):
    scaler = StandardScaler()
    estimator = ["LogisticRegression", LogisticRegression(C=100.0, random_state=1)]

    pipe =  Pipeline([('Scaler', scaler),
                      ('Estimator', estimator[1])])

    pipe.fit(x,y)

    y_pred_pipe = pipe.predict(x)
    accuracy = accuracy_score(y, y_pred_pipe)
    result = [estimator[0], estimator[1], pipe, y_pred_pipe, accuracy]
    #results = []
    results.append(result)
    print(estimator[0], "Accuracy: ",accuracy)
    return results

def parallel(x,y,results,StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline):
    with Manager() as manager:

        tasks = [perceptron, logistic,]
        results = manager.list()
        procs = []
        for task in tasks:
            proc = mp.Process(name=task.__name__, target=task, args=(x,y,results,StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline))
            procs.append(proc)
            print("done with check 1")
            proc.start()
            print("done with check 2")

        for proc in procs:
            print("done with check 3")
            proc.join()
            print("done with check 4")

        results = list(results)
        print("Within WITH")
        print(results)

    print("Within def")
    print(results)
    return results

if __name__ == '__main__':
    __spec__ = "ModuleSpec(name='builtins', loader=<class '_frozen_importlib.BuiltinImporter'>)"

    x, y, StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline, mp, Manager, results = initializer()

    results = parallel(x,y,results,StandardScaler, accuracy_score, Perceptron, LogisticRegression, Pipeline)

    print("Outside of def")
    print(type(results))
    print(len(results))

    print(results[1]) # must be within IF as otherwise does not work ?!?!?!?

    cpu_count = mp.cpu_count()
    print("CPUs: ", cpu_count)

