I have read some articles saying that git bisect is awesome. However, I'm not a native speaker and I can't understand why it's awesome.
Could someone please demonstrate with some code sample:
- How to use it?
- Is it just like
svn blame?
7 Answers
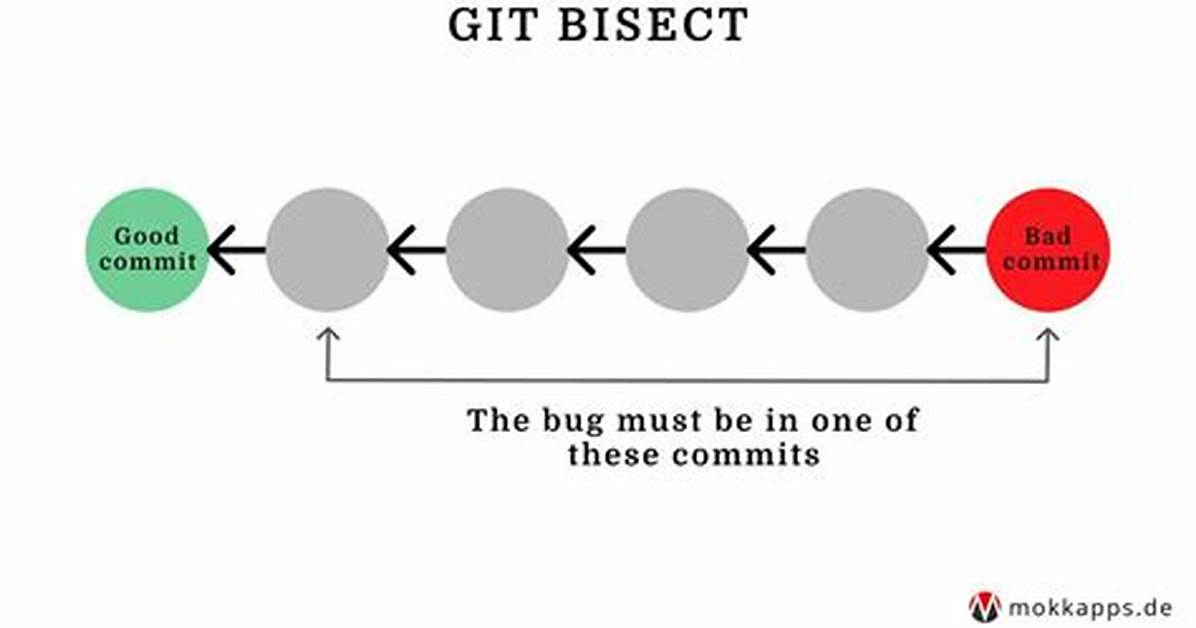
The idea behind git bisect is to perform a binary search in the history to find a particular regression. Imagine that you have the following development history:
... --- 0 --- 1 --- 2 --- 3 --- 4* --- 5 --- current
You know that your program is not working properly at the current revision, and that it was working at the revision 0. So the regression was likely introduced in one of the commits 1, 2, 3, 4, 5, current.
You could try to check out each commit, build it, check if the regression is present or not. If there is a large number of commits, this can take a long time. This is a linear search. We can do better by doing a binary search. This is what the git bisect command does. At each step it tries to reduce the number of revisions that are potentially bad by half.
You'll use the command like this:
$ git stash save
$ git bisect start
$ git bisect bad
$ git bisect good 0
Bisecting: 2 revisions left to test after this (roughly 2 steps)
[< ... sha ... >] 3
After this command, git will checkout a commit. In our case, it'll be commit 3. You need to build your program, and check whether or not the regression is present. You'll also need to tell git the status of this revision with either git bisect bad if the regression is present, or git bisect good if it is not.
Let's suppose that the regression was introduced in commit 4. Then the regression is not present in this revision, and we tell it to git.
$ make
$ make test
... ... ...
$ git bisect good
Bisecting: 0 revisions left to test after this (roughly 1 step)
[< ... sha ... >] 5
It will then checkout another commit. Either 4 or 5 (as there are only two commits). Let's suppose it picked 5. After a build we test the program and see that the regression is present. We then tell it to git:
$ make
$ make test
... ... ...
$ git bisect bad
Bisecting: 0 revisions left to test after this (roughly 0 steps)
[< ... sha ... >] 4
We test the last revision, 4. And since it is the one that introduced the regression, we tell it to git:
$ make
$ make test
... ... ...
$ git bisect bad
< ... sha ... > is the first bad commit
< ... commit message ... >
In this simple situation, we only had to test 3 versions (3, 4, 5) instead of 4 (1, 2, 3, 4). This is a small win, but this is because our history is so small. If the search range is of N commits, we should expect to test 1 + log2 N commits with git bisect instead of roughly N / 2 commits with a linear search.
Once you've found the commit that introduced the regression, you can study it to find the issue. Once this is done, you use git bisect reset to put everything back on the original state before using git bisect command.
git bisect run automatic bisect
If you have an automated ./test script that has exit status 0 iff the test is OK, you can automatically find the bug with bisect run:
git checkout KNOWN_BAD_COMMIT
git bisect start

# Confirm that our test script is correct, and fails on the bad commit.
./test
# Should output != 0.
echo $?
# Tell Git that the current commit is bad.
git bisect bad

# Same for a known good commit in the past.
git checkout KNOWN_GOOD_COMMIT
./test
# Should output 0.
echo $?
# After this, git automatically checks out to the commit
# in the middle of KNOWN_BAD_COMMIT and KNOWN_GOOD_COMMIT.
git bisect good

# Bisect automatically all the way to the first bad or last good rev.
git bisect run ./test

# End the bisect operation and checkout to master again.
git bisect reset
This supposes of course that if the test script ./test is git tracked, that it does not disappear on some earlier commit during bisection.
I have found that very often you can get away by just copying the in-tree script out of tree, and possibly playing with PATH-like variables, and running it from there instead.
Of course, if the test infrastructure on which test depends breaks on older commits, then there is no solution, and you will have to do things manually, deciding how to test commits one by one.
I have found however that using this automation often works, and can be a huge time saver for slower tests lying in your backlog of tasks, where you can just let it run overnight, and possibly have your bug identified by next morning, it is worth the try.

