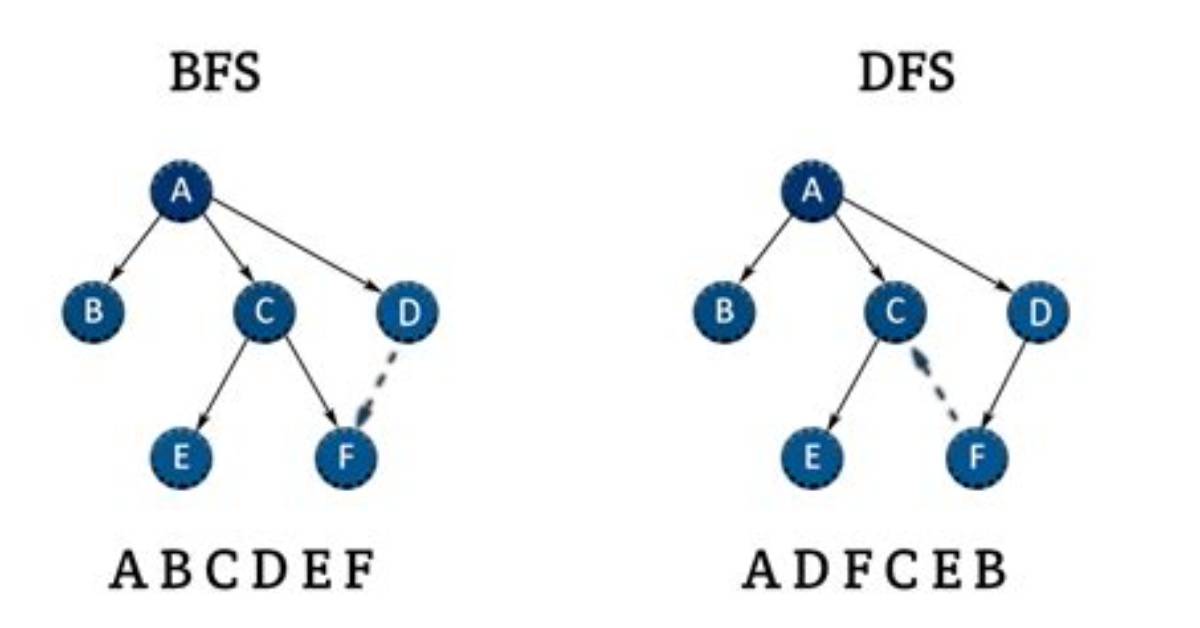
I was revising single source shortest path algorithms and in the video, the teacher mentions that BFS/DFS can't be used directly for finding shortest paths in a weighted graph (I guess everyone knows this already) and said to work out the reason on your own.
I was wondering the exact reason/explanation as to why it can't be used for weighted graphs. Is it due to the weights of the edges or anything else ? Can someone explain me as I feel a little confused.
3 Answers
Consider a graph like this:
A---(3)-----B
|           |
\-(1)-C--(1)/
The shortest path from A to B is via C (with a total weight of 2). A normal BFS will take the path directly from A to B, marking B as seen, and A to C, marking C as seen.
At the next stage, propagating from C, B is already marked as seen, so the path from C to B will not be considered as a potential shorter path, and the BFS will tell you that the shortest path from A to B has a weight of 3.
You can use Dijkstra's algorithm instead of BFS to find the shortest path on a weighted graph. Functionally, the algorithm is very similar to BFS, and can be written in a similar way to BFS. The only thing that changes is the order in which you consider the nodes.
For example, in the above graph, starting at A, a BFS will process A --> B, then A --> C, and stop there because all nodes have been seen.
On the other hand, Dijkstra's algorithm will operate as follows:
- Consider A --> C (since this is the lowest-edge weight from A)
- Consider C --> B (since this is the lowest-weight edge from any node we have reached so far, that we have not yet considered)
- Consider and ignore A --> B since B has already been seen.
Note that the difference lies simply in the order in which edges are inspected. A BFS will consider all edges from a single node before moving on to other nodes, while Dijkstra's algorithm will always consider the lowest-weight unseen edge, from the set of edges connected to all nodes that have been seen so far. It sounds confusing, but the pseudocode is very simple:
create a heap or priority queue
place the starting node in the heap
dist[2...n] = {∞}
dist[1] = 0
while the heap contains items:
   vertex v = top of heap
   pop top of heap
   for each vertex u connected to v:
       if dist[u] > dist[v] + weight of v-->u:
           dist[u] = dist[v] + weight of edge v-->u
           place u on the heap with weight dist[u]
This GIF from Wikipedia provides a good visualisation of what happens:
Notice that this looks very similar to BFS code, the only real difference is the use of a heap, sorted by distance to the node, instead of a regular queue data structure.
Although this is true, but you could use BFS/DFS in weighted graphs, with a little change in the graph, if your graph's weights are positive integers you can replace an edge with weight n with n edges with weight 1 with n-1 middle nodes. Something like this:
A-(4)-B
will be:
A-(1)-M1-(1)-M2-(1)-M3-(1)-B
And don't consider these middle nodes (like M1,M2,M3 ) in your final BFS/DFS results.
This algorithm complexity is O(V * M) and M is the maximum weight of our edges, if we know that in our particular graphs M<log V this algorithm could be considerd, but in general this algorithm may not have a such a good performance.
the teacher mentions that BFS/DFS can't be used directly for finding shortest paths in a weighted graph
For starters, DFS is off the table and doesn't work for shortest paths at all.
Secondly, this answer correctly explains why BFS fails on weighted graphs with cycles and suggests Dijkstra's, replacing the queue with a priority queue and allowing relaxation if a new, shorter path is found to a node.
However, it hasn't been mentioned that on a weighted directed acyclic graph (weighted DAG), Dijkstra's is overkill and a single-source shortest path can be found in O(|V|+|E|) time by relaxing each vertex in topological order. This approach also works for DAGs with negative weight edges.
Here's the high-level algorithm:
distances = {V: infinity for V in vertices}
predecessors = {V: None for V in vertices}

for U in topological_sort(vertices):
    for V in adjacencies(U):
        if distances[V] > distances[U] + edge_weight(U, V): # relax the edge
            distances[V] = distances[U] + edge_weight(U, V)
            predecessors[V] = U
Sources:

