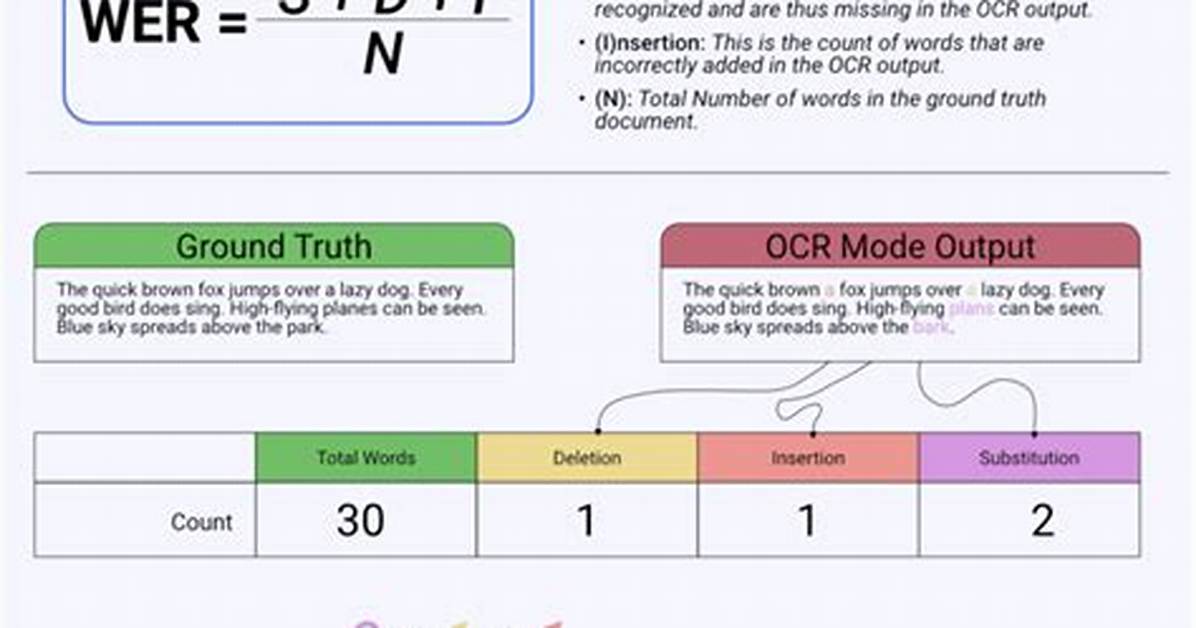
I am trying to compute WER to evaluate an ASR system, but the computation of the score takes a lot of time (since I want to perform some bootstraps on it in order to get confidence intervals for a more robust evaluation of the system).
Here is the code I've come up with so far, does anyone see a more efficient way to do it (faster, and if you have ideas to make it more memory efficient, that would also be welcome).
def modify_text(text):
    """
    Function to modify a clean text to add some errors in it.
    """
    modified_text = []
    for word in true_text:
        action = np.random.choice(['deletion','addition','subsitution','nothing'],
                                   p = [0.1,0.1,0.1,0.7])
        if action in ['addition','substitution']:
            modified_text.append(random.choice(voca))
        if action in ['addition','nothing']:
            modified_text.append(word)
    return modified_text

def wer(s1,s2):

    d = np.zeros([len(s1)+1,len(s2)+1])
    d[:,0] = np.arange(len(s1)+1)
    d[0,:] = np.arange(len(s2)+1)

    for j in range(1,len(s2)+1):
        for i in range(1,len(s1)+1):
            if s1[i-1] == s2[j-1]:
                d[i,j] = d[i-1,j-1]
            else:
                d[i,j] = min(d[i-1,j]+1, d[i,j-1]+1, d[i-1,j-1]+1)

    return d[-1,-1]/len(s1)

text = """I am happy to join with you today in what will go down in history as
the greatest demonstration for freedom in the history of our nation.
Five score years ago, a great American, in whose symbolic shadow
we stand today, signed the Emancipation Proclamation. This momentous
decree came as a great beacon light of hope to millions of Negro slaves
who had been seared in the flames of withering injustice. It came as a
joyous daybreak to end the long night of their captivity. """

true_text = list(tokenize(text))
modified_text = modify_text(true_text)
%timeit wer(true_text,modified_text)
Output:
7.04 ms ± 49.4 µs per loop (mean ± std. dev. of 7 runs, 100 loops each)
Ok this doesn't seem too bad, but I have tens of thousands of texts to evaluate on, with bootstraps, and the texts are way longer. Therefore, I would like to find a faster way to do the wer function. Any idea?
2 Answers
Most speech recognition evaluations first segment the speech into sentences or utterances. Then you compute the WER by aligning each utterance. This can give you a big speedup because the WER computation is O(n^2).
Good to try jiwer package. It does take care of some data cleaning and transformation as well (please see ). It works for me for a medium size of data; it needs to be checked for large data.
Some codes to calculate errors:
    import jitwer
    ground_truth = "ground truth text"
    modified_text = "modified text or output of model to ground truth text"

    # list of transformations you can apply on your text data
    transformation = jiwer.Compose([
        jiwer.ToLowerCase(),
        jiwer.Strip(),
        jiwer.RemoveEmptyStrings(),
        jiwer.RemoveMultipleSpaces(),
        jiwer.RemoveWhiteSpace(replace_by_space=False),
        jiwer.SentencesToListOfWords(word_delimiter=" "),
        jiwer.ExpandCommonEnglishContractions(),
        jiwer.RemoveKaldiNonWords()
    ])

    wer = jiwer.wer(
        ground_truth,
        modified_text,
        truth_transform=transformation,
        hypothesis_transform=transformation
    )
    mer = jiwer.mer(
        ground_truth,
        modified_text,
        truth_transform=transformation,
        hypothesis_transform=transformation
    )
    wil = jiwer.wil(
        ground_truth,
        modified_text,
        truth_transform=transformation,
        hypothesis_transform=transformation
    )
    measures = jiwer.compute_measures(ground_truth, modified_text)

