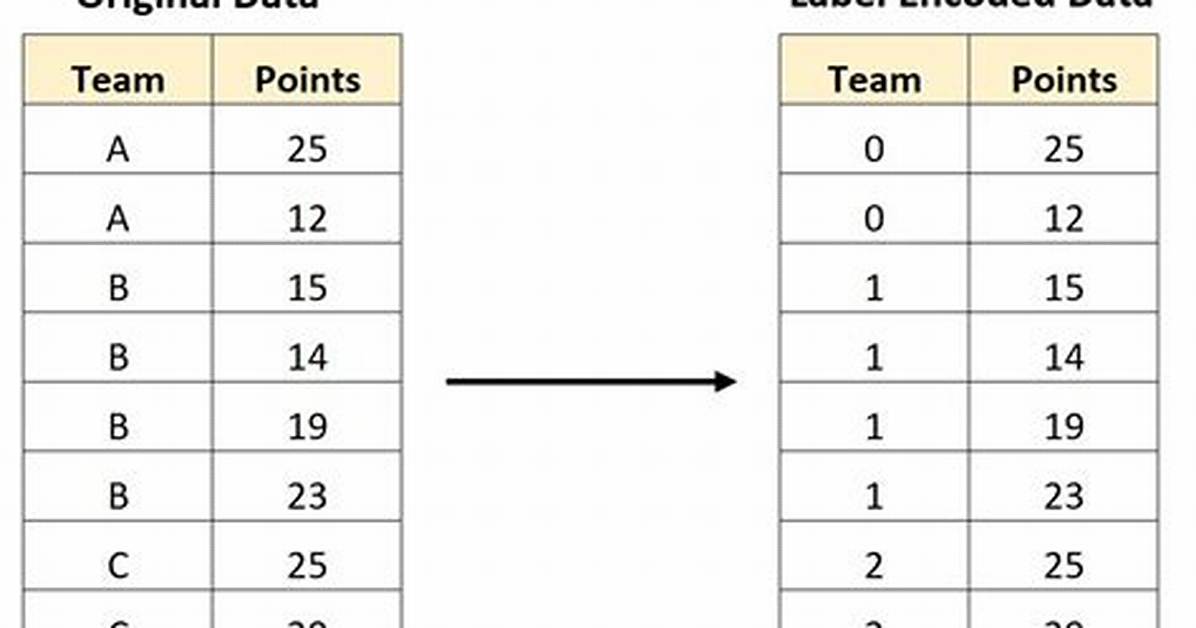
I'm trying to use scikit-learn's LabelEncoder to encode a pandas DataFrame of string labels. As the dataframe has many (50+) columns, I want to avoid creating a LabelEncoder object for each column; I'd rather just have one big LabelEncoder objects that works across all my columns of data.
Throwing the entire DataFrame into LabelEncoder creates the below error. Please bear in mind that I'm using dummy data here; in actuality I'm dealing with about 50 columns of string labeled data, so need a solution that doesn't reference any columns by name.
import pandas
from sklearn import preprocessing

df = pandas.DataFrame({
    'pets': ['cat', 'dog', 'cat', 'monkey', 'dog', 'dog'],
    'owner': ['Champ', 'Ron', 'Brick', 'Champ', 'Veronica', 'Ron'],
    'location': ['San_Diego', 'New_York', 'New_York', 'San_Diego', 'San_Diego',
                 'New_York']
})

le = preprocessing.LabelEncoder()

le.fit(df)
Traceback (most recent call last): File "", line 1, in File "/Users/bbalin/anaconda/lib/python2.7/site-packages/sklearn/preprocessing/label.py", line 103, in fit y = column_or_1d(y, warn=True) File "/Users/bbalin/anaconda/lib/python2.7/site-packages/sklearn/utils/validation.py", line 306, in column_or_1d raise ValueError("bad input shape {0}".format(shape)) ValueError: bad input shape (6, 3)
Any thoughts on how to get around this problem?
24 Answers
You can easily do this though,
df.apply(LabelEncoder().fit_transform)
EDIT2:
In scikit-learn 0.20, the recommended way is
OneHotEncoder().fit_transform(df)
as the OneHotEncoder now supports string input. Applying OneHotEncoder only to certain columns is possible with the ColumnTransformer.
EDIT:
Since this original answer is over a year ago, and generated many upvotes (including a bounty), I should probably extend this further.
For inverse_transform and transform, you have to do a little bit of hack.
from collections import defaultdict
d = defaultdict(LabelEncoder)
With this, you now retain all columns LabelEncoder as dictionary.
# Encoding the variable
fit = df.apply(lambda x: d[x.name].fit_transform(x))

# Inverse the encoded
fit.apply(lambda x: d[x.name].inverse_transform(x))

# Using the dictionary to label future data
df.apply(lambda x: d[x.name].transform(x))
MOAR EDIT:
Using Neuraxle's FlattenForEach step, it's possible to do this as well to use the same LabelEncoder on all the flattened data at once:
FlattenForEach(LabelEncoder(), then_unflatten=True).fit_transform(df)
For using separate LabelEncoders depending for your columns of data, or if only some of your columns of data needs to be label-encoded and not others, then using a ColumnTransformer is a solution that allows for more control on your column selection and your LabelEncoder instances.
As mentioned by larsmans, LabelEncoder() only takes a 1-d array as an argument. That said, it is quite easy to roll your own label encoder that operates on multiple columns of your choosing, and returns a transformed dataframe. My code here is based in part on Zac Stewart's excellent blog post found here.
Creating a custom encoder involves simply creating a class that responds to the fit(), transform(), and fit_transform() methods. In your case, a good start might be something like this:
import pandas as pd
from sklearn.preprocessing import LabelEncoder
from sklearn.pipeline import Pipeline

# Create some toy data in a Pandas dataframe
fruit_data = pd.DataFrame({
    'fruit':  ['apple','orange','pear','orange'],
    'color':  ['red','orange','green','green'],
    'weight': [5,6,3,4]
})

class MultiColumnLabelEncoder:
    def __init__(self,columns = None):
        self.columns = columns # array of column names to encode

    def fit(self,X,y=None):
        return self # not relevant here

    def transform(self,X):
        '''
        Transforms columns of X specified in self.columns using
        LabelEncoder(). If no columns specified, transforms all
        columns in X.
        '''
        output = X.copy()
        if self.columns is not None:
            for col in self.columns:
                output[col] = LabelEncoder().fit_transform(output[col])
        else:
            for colname,col in output.iteritems():
                output[colname] = LabelEncoder().fit_transform(col)
        return output

    def fit_transform(self,X,y=None):
        return self.fit(X,y).transform(X)
Suppose we want to encode our two categorical attributes (fruit and color), while leaving the numeric attribute weight alone. We could do this as follows:
MultiColumnLabelEncoder(columns = ['fruit','color']).fit_transform(fruit_data)
Which transforms our fruit_data dataset from
to
Passing it a dataframe consisting entirely of categorical variables and omitting the columns parameter will result in every column being encoded (which I believe is what you were originally looking for):
MultiColumnLabelEncoder().fit_transform(fruit_data.drop('weight',axis=1))
This transforms
to
.
Note that it'll probably choke when it tries to encode attributes that are already numeric (add some code to handle this if you like).
Another nice feature about this is that we can use this custom transformer in a pipeline:
encoding_pipeline = Pipeline([
    ('encoding',MultiColumnLabelEncoder(columns=['fruit','color']))
    # add more pipeline steps as needed
])
encoding_pipeline.fit_transform(fruit_data)
Since scikit-learn 0.20 you can use sklearn.compose.ColumnTransformer and sklearn.preprocessing.OneHotEncoder:
If you only have categorical variables, OneHotEncoder directly:
from sklearn.preprocessing import OneHotEncoder

OneHotEncoder(handle_unknown='ignore').fit_transform(df)
If you have heterogeneously typed features:
from sklearn.compose import make_column_transformer
from sklearn.preprocessing import RobustScaler
from sklearn.preprocessing import OneHotEncoder

categorical_columns = ['pets', 'owner', 'location']
numerical_columns = ['age', 'weigth', 'height']
column_trans = make_column_transformer(
    (categorical_columns, OneHotEncoder(handle_unknown='ignore'),
    (numerical_columns, RobustScaler())
column_trans.fit_transform(df)
More options in the documentation:
We don't need a LabelEncoder.
You can convert the columns to categoricals and then get their codes. I used a dictionary comprehension below to apply this process to every column and wrap the result back into a dataframe of the same shape with identical indices and column names.
>>> pd.DataFrame({col: df[col].astype('category').cat.codes for col in df}, index=df.index)
   location  owner  pets
0         1      1     0
1         0      2     1
2         0      0     0
3         1      1     2
4         1      3     1
5         0      2     1
To create a mapping dictionary, you can just enumerate the categories using a dictionary comprehension:
>>> {col: {n: cat for n, cat in enumerate(df[col].astype('category').cat.categories)}
     for col in df}

{'location': {0: 'New_York', 1: 'San_Diego'},
 'owner': {0: 'Brick', 1: 'Champ', 2: 'Ron', 3: 'Veronica'},
 'pets': {0: 'cat', 1: 'dog', 2: 'monkey'}}
this does not directly answer your question (for which Naputipulu Jon and PriceHardman have fantastic replies)
However, for the purpose of a few classification tasks etc. you could use
pandas.get_dummies(input_df)
this can input dataframe with categorical data and return a dataframe with binary values. variable values are encoded into column names in the resulting dataframe. more
This is a year-and-a-half after the fact, but I too, needed to be able to .transform() multiple pandas dataframe columns at once (and be able to .inverse_transform() them as well). This expands upon the excellent suggestion of @PriceHardman above:
class MultiColumnLabelEncoder(LabelEncoder):
    """
    Wraps sklearn LabelEncoder functionality for use on multiple columns of a
    pandas dataframe.

    """
    def __init__(self, columns=None):
        self.columns = columns

    def fit(self, dframe):
        """
        Fit label encoder to pandas columns.

        Access individual column classes via indexig `self.all_classes_`

        Access individual column encoders via indexing
        `self.all_encoders_`
        """
        # if columns are provided, iterate through and get `classes_`
        if self.columns is not None:
            # ndarray to hold LabelEncoder().classes_ for each
            # column; should match the shape of specified `columns`
            self.all_classes_ = np.ndarray(shape=self.columns.shape,
                                           dtype=object)
            self.all_encoders_ = np.ndarray(shape=self.columns.shape,
                                            dtype=object)
            for idx, column in enumerate(self.columns):
                # fit LabelEncoder to get `classes_` for the column
                le = LabelEncoder()
                le.fit(dframe.loc[:, column].values)
                # append the `classes_` to our ndarray container
                self.all_classes_[idx] = (column,
                                          np.array(le.classes_.tolist(),
                                                  dtype=object))
                # append this column's encoder
                self.all_encoders_[idx] = le
        else:
            # no columns specified; assume all are to be encoded
            self.columns = dframe.iloc[:, :].columns
            self.all_classes_ = np.ndarray(shape=self.columns.shape,
                                           dtype=object)
            for idx, column in enumerate(self.columns):
                le = LabelEncoder()
                le.fit(dframe.loc[:, column].values)
                self.all_classes_[idx] = (column,
                                          np.array(le.classes_.tolist(),
                                                  dtype=object))
                self.all_encoders_[idx] = le
        return self

    def fit_transform(self, dframe):
        """
        Fit label encoder and return encoded labels.

        Access individual column classes via indexing
        `self.all_classes_`

        Access individual column encoders via indexing
        `self.all_encoders_`

        Access individual column encoded labels via indexing
        `self.all_labels_`
        """
        # if columns are provided, iterate through and get `classes_`
        if self.columns is not None:
            # ndarray to hold LabelEncoder().classes_ for each
            # column; should match the shape of specified `columns`
            self.all_classes_ = np.ndarray(shape=self.columns.shape,
                                           dtype=object)
            self.all_encoders_ = np.ndarray(shape=self.columns.shape,
                                            dtype=object)
            self.all_labels_ = np.ndarray(shape=self.columns.shape,
                                          dtype=object)
            for idx, column in enumerate(self.columns):
                # instantiate LabelEncoder
                le = LabelEncoder()
                # fit and transform labels in the column
                dframe.loc[:, column] =\
                    le.fit_transform(dframe.loc[:, column].values)
                # append the `classes_` to our ndarray container
                self.all_classes_[idx] = (column,
                                          np.array(le.classes_.tolist(),
                                                  dtype=object))
                self.all_encoders_[idx] = le
                self.all_labels_[idx] = le
        else:
            # no columns specified; assume all are to be encoded
            self.columns = dframe.iloc[:, :].columns
            self.all_classes_ = np.ndarray(shape=self.columns.shape,
                                           dtype=object)
            for idx, column in enumerate(self.columns):
                le = LabelEncoder()
                dframe.loc[:, column] = le.fit_transform(
                        dframe.loc[:, column].values)
                self.all_classes_[idx] = (column,
                                          np.array(le.classes_.tolist(),
                                                  dtype=object))
                self.all_encoders_[idx] = le
        return dframe.loc[:, self.columns].values

    def transform(self, dframe):
        """
        Transform labels to normalized encoding.
        """
        if self.columns is not None:
            for idx, column in enumerate(self.columns):
                dframe.loc[:, column] = self.all_encoders_[
                    idx].transform(dframe.loc[:, column].values)
        else:
            self.columns = dframe.iloc[:, :].columns
            for idx, column in enumerate(self.columns):
                dframe.loc[:, column] = self.all_encoders_[idx]\
                    .transform(dframe.loc[:, column].values)
        return dframe.loc[:, self.columns].values

    def inverse_transform(self, dframe):
        """
        Transform labels back to original encoding.
        """
        if self.columns is not None:
            for idx, column in enumerate(self.columns):
                dframe.loc[:, column] = self.all_encoders_[idx]\
                    .inverse_transform(dframe.loc[:, column].values)
        else:
            self.columns = dframe.iloc[:, :].columns
            for idx, column in enumerate(self.columns):
                dframe.loc[:, column] = self.all_encoders_[idx]\
                    .inverse_transform(dframe.loc[:, column].values)
        return dframe.loc[:, self.columns].values
Example:
If df and df_copy() are mixed-type pandas dataframes, you can apply the MultiColumnLabelEncoder() to the dtype=object columns in the following way:
# get `object` columns
df_object_columns = df.iloc[:, :].select_dtypes(include=['object']).columns
df_copy_object_columns = df_copy.iloc[:, :].select_dtypes(include=['object']).columns

# instantiate `MultiColumnLabelEncoder`
mcle = MultiColumnLabelEncoder(columns=object_columns)

# fit to `df` data
mcle.fit(df)

# transform the `df` data
mcle.transform(df)

# returns output like below
array([[1, 0, 0, ..., 1, 1, 0],
       [0, 5, 1, ..., 1, 1, 2],
       [1, 1, 1, ..., 1, 1, 2],
       ...,
       [3, 5, 1, ..., 1, 1, 2],

# transform `df_copy` data
mcle.transform(df_copy)

# returns output like below (assuming the respective columns
# of `df_copy` contain the same unique values as that particular
# column in `df`
array([[1, 0, 0, ..., 1, 1, 0],
       [0, 5, 1, ..., 1, 1, 2],
       [1, 1, 1, ..., 1, 1, 2],
       ...,
       [3, 5, 1, ..., 1, 1, 2],

# inverse `df` data
mcle.inverse_transform(df)

# outputs data like below
array([['August', 'Friday', '2013', ..., 'N', 'N', 'CA'],
       ['April', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['August', 'Monday', '2014', ..., 'N', 'N', 'NJ'],
       ...,
       ['February', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['April', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['March', 'Tuesday', '2013', ..., 'N', 'N', 'NJ']], dtype=object)

# inverse `df_copy` data
mcle.inverse_transform(df_copy)

# outputs data like below
array([['August', 'Friday', '2013', ..., 'N', 'N', 'CA'],
       ['April', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['August', 'Monday', '2014', ..., 'N', 'N', 'NJ'],
       ...,
       ['February', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['April', 'Tuesday', '2014', ..., 'N', 'N', 'NJ'],
       ['March', 'Tuesday', '2013', ..., 'N', 'N', 'NJ']], dtype=object)
You can access individual column classes, column labels, and column encoders used to fit each column via indexing:
mcle.all_classes_
mcle.all_encoders_
mcle.all_labels_
It is possible to do this all in pandas directly and is well-suited for a unique ability of the replace method.
First, let's make a dictionary of dictionaries mapping the columns and their values to their new replacement values.
transform_dict = {}
for col in df.columns:
    cats = pd.Categorical(df[col]).categories
    d = {}
    for i, cat in enumerate(cats):
        d[cat] = i
    transform_dict[col] = d

transform_dict
{'location': {'New_York': 0, 'San_Diego': 1},
 'owner': {'Brick': 0, 'Champ': 1, 'Ron': 2, 'Veronica': 3},
 'pets': {'cat': 0, 'dog': 1, 'monkey': 2}}
Since this will always be a one to one mapping, we can invert the inner dictionary to get a mapping of the new values back to the original.
inverse_transform_dict = {}
for col, d in transform_dict.items():
    inverse_transform_dict[col] = {v:k for k, v in d.items()}

inverse_transform_dict
{'location': {0: 'New_York', 1: 'San_Diego'},
 'owner': {0: 'Brick', 1: 'Champ', 2: 'Ron', 3: 'Veronica'},
 'pets': {0: 'cat', 1: 'dog', 2: 'monkey'}}
Now, we can use the unique ability of the replace method to take a nested list of dictionaries and use the outer keys as the columns, and the inner keys as the values we would like to replace.
df.replace(transform_dict)
   location  owner  pets
0         1      1     0
1         0      2     1
2         0      0     0
3         1      1     2
4         1      3     1
5         0      2     1
We can easily go back to the original by again chaining the replace method
df.replace(transform_dict).replace(inverse_transform_dict)
    location     owner    pets
0  San_Diego     Champ     cat
1   New_York       Ron     dog
2   New_York     Brick     cat
3  San_Diego     Champ  monkey
4  San_Diego  Veronica     dog
5   New_York       Ron     dog
Assuming you are simply trying to get a sklearn.preprocessing.LabelEncoder() object that can be used to represent your columns, all you have to do is:
le.fit(df.columns)
In the above code you will have a unique number corresponding to each column.
More precisely, you will have a 1:1 mapping of df.columns to le.transform(df.columns.get_values()). To get a column's encoding, simply pass it to le.transform(...). As an example, the following will get the encoding for each column:
le.transform(df.columns.get_values())
Assuming you want to create a sklearn.preprocessing.LabelEncoder() object for all of your row labels you can do the following:
le.fit([y for x in df.get_values() for y in x])
In this case, you most likely have non-unique row labels (as shown in your question). To see what classes the encoder created you can do le.classes_. You'll note that this should have the same elements as in set(y for x in df.get_values() for y in x). Once again to convert a row label to an encoded label use le.transform(...). As an example, if you want to retrieve the label for the first column in the df.columns array and the first row, you could do this:
le.transform([df.get_value(0, df.columns[0])])
The question you had in your comment is a bit more complicated, but can still be accomplished:
le.fit([str(z) for z in set((x[0], y) for x in df.iteritems() for y in x[1])])
The above code does the following:
- Make a unique combination of all of the pairs of (column, row)
- Represent each pair as a string version of the tuple. This is a workaround to overcome the
LabelEncoderclass not supporting tuples as a class name. - Fits the new items to the
LabelEncoder.
Now to use this new model it's a bit more complicated. Assuming we want to extract the representation for the same item we looked up in the previous example (the first column in df.columns and the first row), we can do this:
le.transform([str((df.columns[0], df.get_value(0, df.columns[0])))])
Remember that each lookup is now a string representation of a tuple that contains the (column, row).
No, LabelEncoder does not do this. It takes 1-d arrays of class labels and produces 1-d arrays. It's designed to handle class labels in classification problems, not arbitrary data, and any attempt to force it into other uses will require code to transform the actual problem to the problem it solves (and the solution back to the original space).
If you have numerical and categorical both type of data in dataframe You can use : here X is my dataframe having categorical and numerical both variables
from sklearn import preprocessing
le = preprocessing.LabelEncoder()

for i in range(0,X.shape[1]):
    if X.dtypes[i]=='object':
        X[X.columns[i]] = le.fit_transform(X[X.columns[i]])
Note: This technique is good if you are not interested in converting them back.
After lots of search and experimentation with some answers here and elsewhere, I think your answer is here:
pd.DataFrame(columns=df.columns, data=LabelEncoder().fit_transform(df.values.flatten()).reshape(df.shape))
This will preserve category names across columns:
import pandas as pd
from sklearn.preprocessing import LabelEncoder

df = pd.DataFrame([['A','B','C','D','E','F','G','I','K','H'],
                   ['A','E','H','F','G','I','K','','',''],
                   ['A','C','I','F','H','G','','','','']],
                  columns=['A1', 'A2', 'A3','A4', 'A5', 'A6', 'A7', 'A8', 'A9', 'A10'])

pd.DataFrame(columns=df.columns, data=LabelEncoder().fit_transform(df.values.flatten()).reshape(df.shape))

    A1  A2  A3  A4  A5  A6  A7  A8  A9  A10
0   1   2   3   4   5   6   7   9   10  8
1   1   5   8   6   7   9   10  0   0   0
2   1   3   9   6   8   7   0   0   0   0
I checked the source code () of LabelEncoder. It was based on a set of numpy transformation, which one of those is np.unique(). And this function only takes 1-d array input. (correct me if I am wrong).
Very Rough ideas... first, identify which columns needed LabelEncoder, then loop through each column.
def cat_var(df):
    """Identify categorical features.

    Parameters
    ----------
    df: original df after missing operations

    Returns
    -------
    cat_var_df: summary df with col index and col name for all categorical vars
    """
    col_type = df.dtypes
    col_names = list(df)

    cat_var_index = [i for i, x in enumerate(col_type) if x=='object']
    cat_var_name = [x for i, x in enumerate(col_names) if i in cat_var_index]

    cat_var_df = pd.DataFrame({'cat_ind': cat_var_index,
                               'cat_name': cat_var_name})

    return cat_var_df


from sklearn.preprocessing import LabelEncoder

def column_encoder(df, cat_var_list):
    """Encoding categorical feature in the dataframe

    Parameters
    ----------
    df: input dataframe
    cat_var_list: categorical feature index and name, from cat_var function

    Return
    ------
    df: new dataframe where categorical features are encoded
    label_list: classes_ attribute for all encoded features
    """

    label_list = []
    cat_var_df = cat_var(df)
    cat_list = cat_var_df.loc[:, 'cat_name']

    for index, cat_feature in enumerate(cat_list):

        le = LabelEncoder()

        le.fit(df.loc[:, cat_feature])
        label_list.append(list(le.classes_))

        df.loc[:, cat_feature] = le.transform(df.loc[:, cat_feature])

    return df, label_list
The returned df would be the one after encoding, and label_list will show you what all those values means in the corresponding column. This is a snippet from a data process script I wrote for work. Let me know if you think there could be any further improvement.
EDIT: Just want to mention here that the methods above work with data frame with no missing the best. Not sure how it is working toward data frame contains missing data. (I had a deal with missing procedure before execute above methods)
A short way to LabelEncoder() multiple columns with a dict():
from sklearn.preprocessing import LabelEncoder
le_dict = {col: LabelEncoder() for col in columns }
for col in columns:
    le_dict[col].fit_transform(df[col])
and you can use this le_dict to labelEncode any other column:
le_dict[col].transform(df_another[col])
Using Neuraxle
TLDR; You here can use the FlattenForEach wrapper class to simply transform your df like:
FlattenForEach(LabelEncoder(), then_unflatten=True).fit_transform(df).
With this method, your label encoder will be able to fit and transform within a regular scikit-learn Pipeline. Let's simply import:
from sklearn.preprocessing import LabelEncoder
from neuraxle.steps.column_transformer import ColumnTransformer
from neuraxle.steps.loop import FlattenForEach
Same shared encoder for columns:
Here is how one shared LabelEncoder will be applied on all the data to encode it:
p = FlattenForEach(LabelEncoder(), then_unflatten=True)
Result:
    p, predicted_output = p.fit_transform(df.values)
    expected_output = np.array([
        [6, 7, 6, 8, 7, 7],
        [1, 3, 0, 1, 5, 3],
        [4, 2, 2, 4, 4, 2]
    ]).transpose()
    assert np.array_equal(predicted_output, expected_output)

