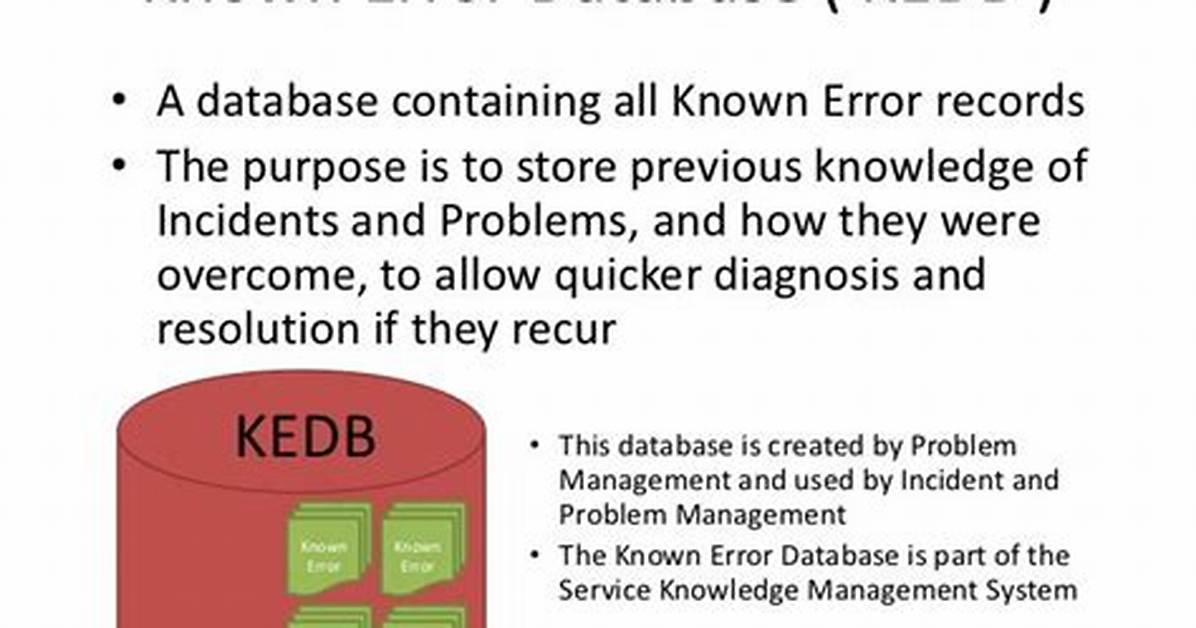
ITIL is a set of best practices that help IT teams function efficiently and align with the needs of business. One important piece of the ITIL that contributes to both of these goals is the Known Error Database, often shortened to KEDB. This is a database that tracks and describes all of the known errors within an overall system.
In this article, we are looking at the uses and benefits of employing KEDBs to align IT with the overall enterprise.
Defining a Known Error Database
To understand what a KEDB is and its importance to an IT team and the wider customers, let’s review a couple ITIL terms. (Remember that ITIL is formerly known as the Information Technology Infrastructure Library. ITIL provides detailed best practices for IT service management, known as ITSM.)
- An incident is an unscheduled interruption in an IT service. This could mean email service went down without notice, it could mean some software stopped interfacing with other software, etc.
- A problem is the root cause of the incident; it’s what made the incident happen, though it may take some time to identify the problem after the incident occurs.
- Once the problem is identified, it is no longer a problem, but a known error – the IT team knows what is causing an incident and what the issue it, but it hasn’t yet been solved.
The distinction between an incident and a problem are significant – many users may report outages or interruptions, but IT may not know the problem, the underlying cause. When IT is able to uncover the problem that caused the incident, they can start to solve it, either with a short-term workaround or a long-term resolution.
A known error database, then, tracks all of the known errors within the IT’s jurisdiction, which is typically an entire system or even organization. Ideally, the KEDB includes:
- Descriptions of how/when the issue will appear, including a description of the incident from the user’s point of view
- Screenshots of the incident(s) and problem
- Text of error messages
- Workarounds (temporary solutions) that help the user handle the problem and return to productive work with minor to no delay
- Resolutions, if the incident and problem have occurred and previously been solved
Temporary workarounds vs. permanent solutions
Once IT can determine the problem of an incident, they have two routes to solutions.
- The first is to find a long-term, permanent solution. Depending how complicated the problem and whether it has occurred before, IT must prioritize the time and resources it will take to find a permanent solution as well as how widespread and serious the problem is. This can mean some problems are de-prioritized.
- The second route is to determine a short-term workaround. A workaround is a temporary fix that allows work to happen until the problem is resolved permanently. Workarounds are vital, as IT must prioritize how to spend time and money to solve which problems.
Situations that have been de-escalated from needing a long-term solution means that users may continue to experience the incident. When users repeatedly run into the incident, a workaround to the problem ensures that the user has only a minimum stoppage in productive work.

