Machine learning is augmenting human capabilities and making things possible—things that just a few years back were considered impossible.
Take, for example, the protein folding problem. For about 50 years, the biology field assumed that solving this problem was beyond human capabilities. But with the might of AI and ML, folks at DeepMind were finally able to come up with a solution to this problem.
ML-based applications are ubiquitous these days and they continue to evolve day by day. Before long we might also manage to build a fully autonomous driving vehicle.
But then the question arises: how exactly do you make a machine learn?
Let’s look at the two most well-known machine learning methods—supervised and unsupervised learning. We’ll deep dive into how they both work, and we’ll look at up-and-coming learning methods, too.
Machines can learn
We are very familiar with the paradigm of coding programs. Coding is akin to explicitly telling the machine what to do. The programmed machine cannot make a decision on its own. And it most certainly cannot handle a situation that it hasn’t been programmed for.
This is like giving machines a fish when, really, we want to teach machines how to fish.
In the field of AI and ML the way machines are made to learn generally fall under two categories:
- Supervised learning
- Unsupervised learning
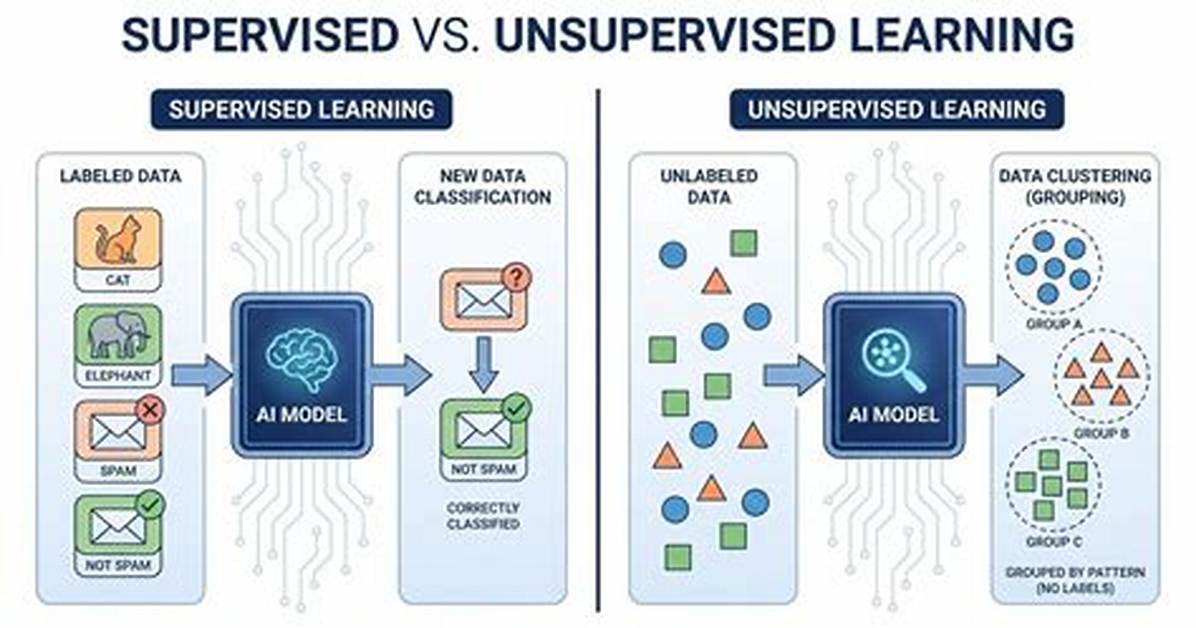
In a nutshell, the difference between these two methods is that in supervised learning we also provide the correct results in terms of labeled data. Labeled data in machine learning parlance means that we know the correct output values of the data beforehand.
In unsupervised machine learning, the data is not labeled. So, in unsupervised learning the machines are left to fend for themselves, you may ask? Not quite.
(Understand the role of data annotation in ML.)
How supervised machine learning works
The notion of ‘supervision’ in supervised machine learning comes from the labeled data.
With the help of labels, the predictions a machine learning model makes can be compared against the known correct values. This helps with gauging the accuracy of the model and calculation of loss. This in turn can be used as a feedback to the model to further improve its predictions. (This labeled data seems like the answer to all our problems, right? What could ever go wrong!)
But, as they say: with great power comes great responsibilities. We need to be careful with the extent we used the labels in during the supervised learning or in machine learning jargon how much we train our model.
The pitfall of too much training is overfitting. This is what happens when the ML model learns the training data so well that, when new data comes in, the model often fails to perform correctly.
(Unsupervised learning algorithm can also face overfitting, but it is more prevalent in supervised learning algorithms. Eagerness to train one more epoch, for the sake of better accuracy, often leads into overfitting.)
Broadly, supervised machine learning finds its application in 2 types of tasks:
- Classification
- Regression
Classification
In this type of tasks, the model tries to classify a given input into one of the data categories.
For example, classifying a tumor as malignant or benign. Here we train the model on the input data which has already been correctly labeled with either malignant or benign. We compare the generated output with these labels and re-train the model to achieve a robust model.
Regression
In this type of tasks, the model tries to predict a numerical value (real number).
An example of this is predicting housing prices given housing data. The key point here is that the output in this case is a real or continuous value—it’s not one bucket or the other, as in classification. Again, we compare the predicted value with the known correct values and make further tweaks to improve the model.
As you can see, in both classification and regression, the labels themselves are, in a sense, “supervising” the training of the machine learning model.

