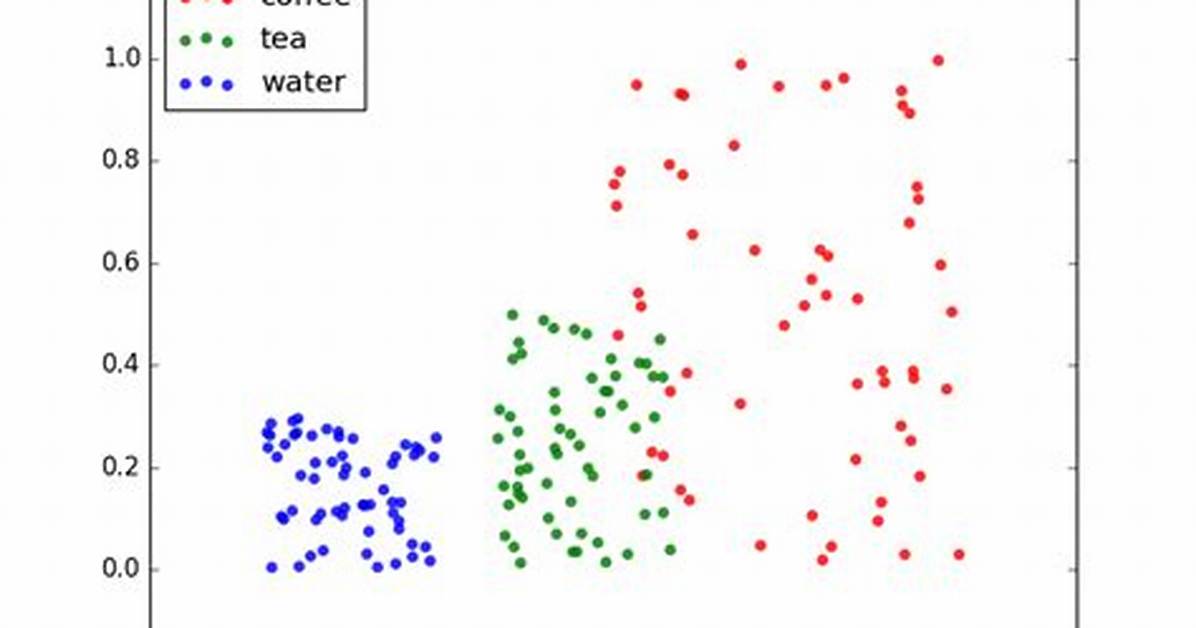
In this article, we’ll explain how to get started with Matplotlib scatter and line plots.
(This article is part of our Data Visualization Guide. Use the right-hand menu to navigate.)
Install Zeppelin
First, download and install Zeppelin, a graphical Python interpreter which we’ve previously discussed. After all, you can’t graph from the Python shell, as that is not a graphical environment.
Start Zeppelin. If you are using a virtual Python environment you will need to source that environment (e.g., source py34/bin/activate) just like you’re running Python as a regular user. This way, NumPy and Matplotlib will be imported, which you need to install using pip.
First plot
Here is the simplest plot: x against y. The two arrays must be the same size since the numbers plotted picked off the array in pairs: (1,2), (2,2), (3,3), (4,4).
We use plot(), we could also have used scatter(). They are almost the same. This is because plot() can either draw a line or make a scatter plot. The differences are explained below.
import numpy as np
import matplotlib.pyplot as plt
x = [1,2,3,4]
y = [1,2,3,4]
plt.plot(x,y)
plt.show()
Results in:
You can feed any number of arguments into the plot() function. The format is plt.plot(x,y,colorOptions, *args, **kargs). *args and **kargs lets you pass values to other objects, which we illustrate below.
If you only give plot() one value, it assumes that is the y coordinate. If you put dashes (“–“) after the color name, then it draws a line between each point, i.e., makes a line chart, rather than plotting points, i.e., a scatter plot. Leave off the dashes and the color becomes the point market, which can be a triangle (“v”), circle (“o”), etc.
Here we use np.array() to create a NumPy array. Even without doing so, Matplotlib converts arrays to NumPy arrays internally. NumPy is your best option for data science work because of its rich set of features.

