Machine learning. Data science. Artificial intelligence. Deep learning. Statistics. Most organizations, companies and individuals today are using these technologies – whether they know it or not. If your work involves computers, you’re likely familiar with at least some of them – but the terms can be confusing, and their use sometimes conflicting.
The 21st century is the era of big data. Big data refers to data sets that are so large and complex that previous applications of data processing aren’t adequate. Researchers and companies are harnessing and experimenting with various methods of extracting value from big data. The global connected world offers infinite ways to generate, collect, and store data for analysis. Never before have we had access to this much data, and we are only now beginning to find ways to unleash the immense amount of meaning and information contained within.
The relatively recent concepts of data science, machine learning, and deep learning offer a new set of techniques and methods, but also find their way into hype and branding. Companies may adopt these terms without necessarily using their processes for a “cutting-edge” appeal to customers. In this article, we’ll explore the differences between these terms, whether they’re new or a return of the old, and whether they’re just different names for the same thing.
Statistics and artificial intelligence
Let’s begin with statistics, as these fields have been around for decades, even centuries, before computers were invented. The study of statistics and the application of statistical modeling are a subfield of mathematics. Both the theories and applications are aimed at identifying and formalizing relationships in data variables, based on mathematical equations. Statistical modeling relies on tools like samples, populations, and hypotheses.
In the latter part of 20th century, as access to computers became more widely available and computational power commoditized, people began to do statistics in computational applications. This allowed for treatment of larger and different data sets as well as the application of statistical methods that were untenable without computing power.
Artificial Intelligence is ultimately an evolution of this first encounter between math and computer science. [For a fun romp through the history of AI, check this out] Statistical modeling started as a purely mathematical or scientific exercise, but when it became computational, the door opened to using statistics to solve ‘human’ problems. In the post-war, due to enthusiastic optimism around the promise of computing as well as the belief that human thought processes were essentially computational, the idea that we could build an ‘artificial’ human intelligence gained currency.
In the 1960s, the field of artificial intelligence was formalized into a subset of computer science. New technology and a more expansive understanding of how humans’ minds work changed artificial intelligence, from the original computational statistics paradigm to the modern idea that machines could mimic actual human capabilities, such as decision making and performing more “human” tasks.
Modern artificial intelligence is often broken into two areas: general artificial intelligence and applied artificial intelligence. Applied artificial intelligence is at play when we consider systems like driverless cars or machines that can smartly trade stocks. Much less common in practice is general artificial intelligence, the concept that a system could, in theory, handle any task, such as:
- Planning
- Getting around
- Recognizing objects and sounds
- Speaking and translating
- Performing social or business transactions
- Working creatively
The concept of artificial intelligence grows and shifts as technology advances, and likely will do so for the foreseeable future. Currently the only solid criterion for success or failure is how it can accomplish applied tasks.
Machine learning
By 1959, the idea of artificial intelligence had gained solid traction in computer science. Arthur Samuel, a leader and expert in the field, imagined that instead of engineers “teaching” or programming computers to have what they need to carry out tasks, that perhaps computers could teach themselves – learn something without being explicitly programmed to do so. Samuel called this “machine learning”.
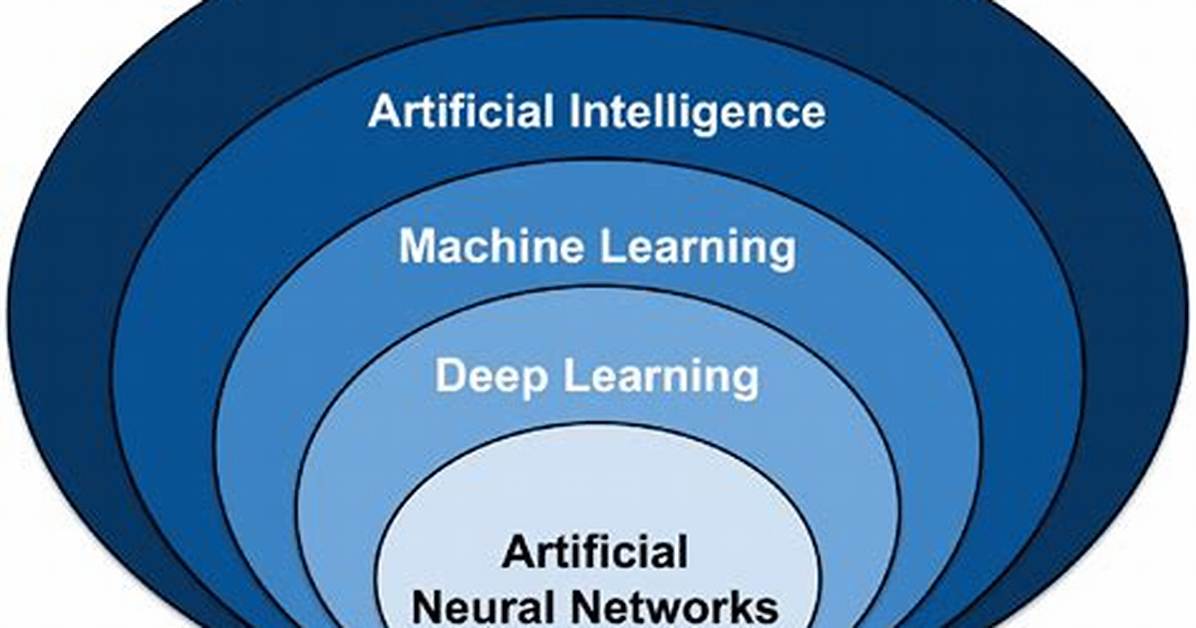
Machine learning is a form of applied artificial intelligence, based on the theory that systems that can change actions and responses as they are exposed to more data will be more efficient, scalable and adaptable for certain applications compared to those explicitly programmed (by humans). There are certainly many current applications proving this point: navigation apps and recommendation engines (shopping, shows, etc.) being two of the obvious examples.
Machine learning is typically categorized as either ‘supervised’ or ‘unsupervised’. Supervised learning involves the machine to infer functions from known inputs to known outputs. Unsupervised MACHINE LEARNING works with the inputs only, transforming or finding patterns in the data itself without a known or expected output. For a more detailed discussion, see my blog about the differences between supervised and unsupervised machine learning.
Machine learning is a task-oriented application of statistical transformations. Accomplishing the task will require a process or set of steps, rules, etc. The process or set of rules to be followed in calculations or problem-solving operations is called an algorithm. When designing a learning machine, the engineer programs a set of algorithms through which the machine will process data.
As the machine learns – gets feedback – it typically will not change the employed statistical transformations but rather alter the algorithm. For example, if the machine is trained to factor two criteria in evaluating data and it learns that a third criteria has high correlation to the other two and refines the accuracy of calculation, it could add that third criteria to the analysis. This would be a change to the steps (algorithm), but not the underlying math.
Ultimately, machine learning is a way to “teach” computers to be adaptable to changes in data. We now have essentially infinite amounts of digital data being created constantly. The volume and diversity of that data increases rapidly and exponentially. Machines analysis has the advantages of speed, accuracy and lack of bias over human analysis, which is why machine learning is critical and has hit a tipping point.

