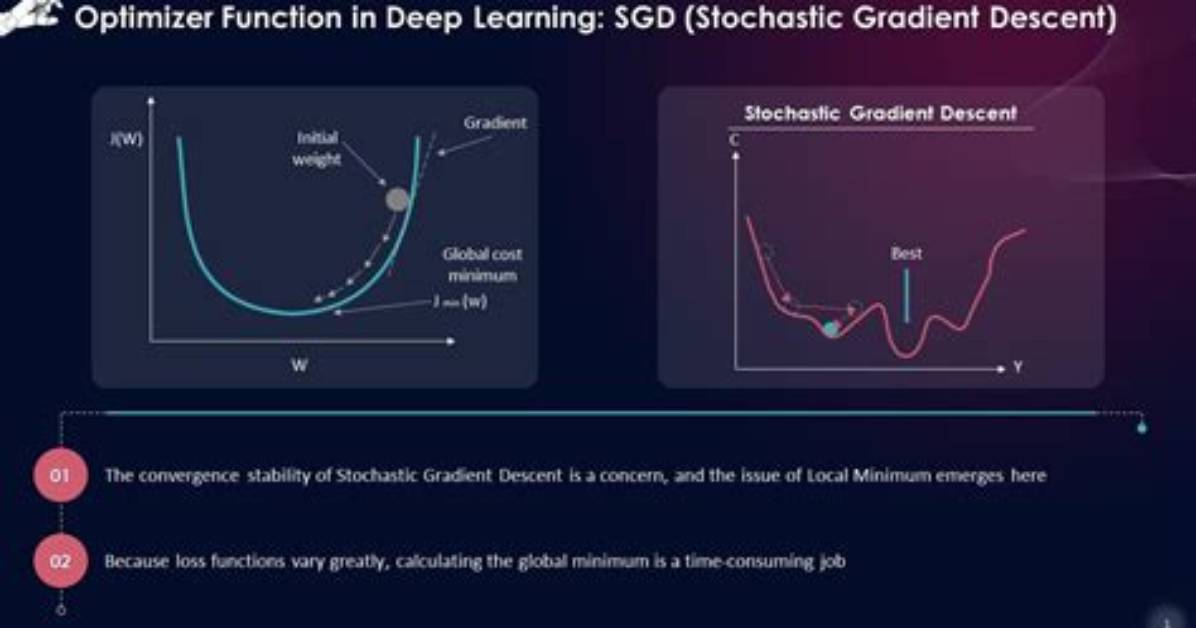
In SGD, the optimizer estimates the direction of steepest descent based on a mini-batch and takes a step in this direction. Because the step size is fixed, SGD can quickly get stuck on plateaus or in local minima. Update Rule for SGD with Momentum (PyTorch, 20.07.
Why do we use SGD Optimizer?
So, in SGD, we find out the gradient of the cost function of a single example at each iteration instead of the sum of the gradient of the cost function of all the examples. ... Hence, in most scenarios, SGD is preferred over Batch Gradient Descent for optimizing a learning algorithm.
Is Adam optimizer better than SGD?
Adam is great, it's much faster than SGD, the default hyperparameters usually works fine, but it has its own pitfall too. Many accused Adam has convergence problems that often SGD + momentum can converge better with longer training time. We often see a lot of papers in 2018 and 2019 were still using SGD.

