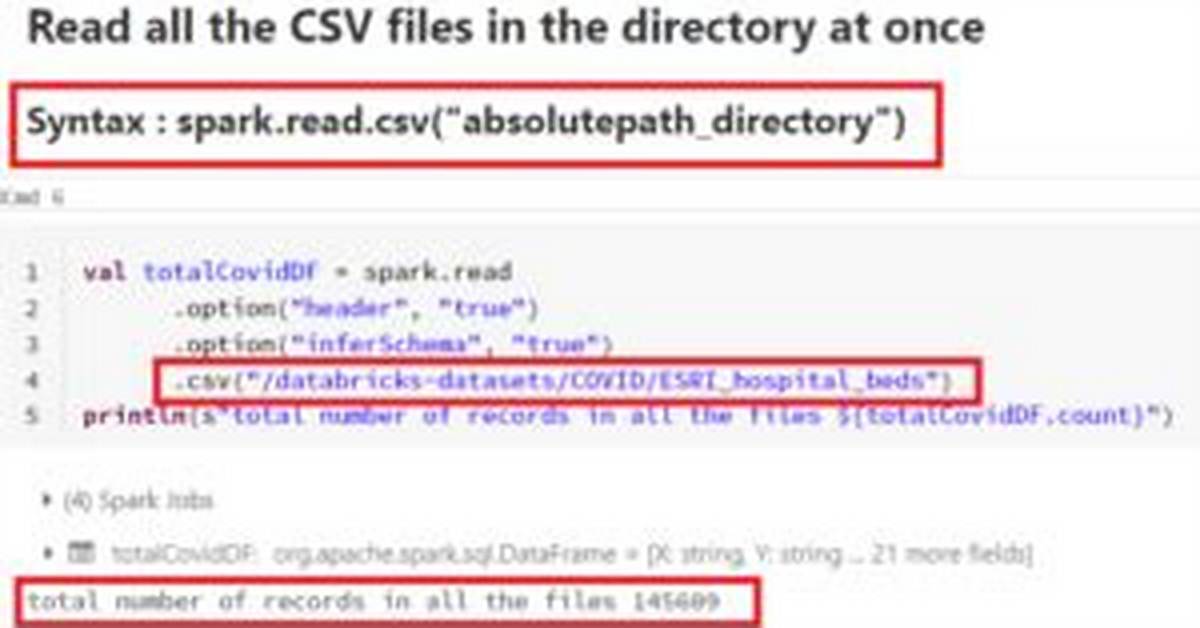
To read a CSV file you must first create a DataFrameReader and set a number of options.
df=spark.read.format(“csv”).option(“header”,”true”).load(filePath)csvSchema = StructType([StructField(“id”,IntegerType(),False)])df=spark.read.format(“csv”).schema(csvSchema).load(filePath)
Is Spark Read CSV an action?
It’s something that is in the optimization & performance aspect and cannot be seen as Action or Transformation.
How do I read a CSV GZ file in Spark?
Have you tried this solution using multiple csv. gzip files? It would be really awesome if that works. – Cesar A. You can use the * wildcard – df = spark.read.option(“header”, “true”).csv(“some_path/*.gz”) . It works across several folders too- df = spark.read.option(“header”, “true”).csv(“some_path/*/*.gz”) – Tim496.
How do I read a Spark file?
There are three ways to read text files into PySpark DataFrame.
Using spark.read.text()Using spark.read.csv()Using spark.read.format().load()
What is RDD in Spark?
RDD was the primary user-facing API in Spark since its inception. At the core, an RDD is an immutable distributed collection of elements of your data, partitioned across nodes in your cluster that can be operated in parallel with a low-level API that offers transformations and actions.
How do I read a CSV file in Python?
Reading a CSV using Python’s inbuilt module called csv using csv.
2.1 Using csv. reader
Import the csv library. import csv.Open the CSV file. The . Use the csv.reader object to read the CSV file. csvreader = csv.reader(file)Extract the field names. Create an empty list called header. Extract the rows/records. Close the file.
How do I create a DataFrame in Spark?
There are three ways to create a DataFrame in Spark by hand:
Create a list and parse it as a DataFrame using the toDataFrame() method from the SparkSession .Convert an RDD to a DataFrame using the toDF() method.Import a file into a SparkSession as a DataFrame directly.
How do I create a CSV file in Spark?
In order to explain first let’s create a DataFrame either from data or by reading a CSV file into Spark DataFrame.
Spark Write DataFrame to CSV File
Spark Write DataFrame as CSV with Header. Save CSV File Using Options. Save DataFrame as CSV to S3. Save DataFrame as CSV to HDFS. Save Modes. Conclusion.
Is GZ same as gzip?
Gzip is one of the most popular compression algorithms that allow you to reduce the size of a file and keep the original file mode, ownership, and timestamp. Gzip also refers to the . gz file format and the gzip utility which is used to compress and decompress files.
What is .GZ file type?
GZIP is the file format, and GZ is the file extension used for GZIP compressed files.
How do I read a TXT GZ file in Pyspark?
Spark document clearly specify that you can read gz file automatically: All of Spark’s file-based input methods, including textFile, support running on directories, compressed files, and wildcards as well. For example, you can use textFile(“/my/directory”), textFile(“/my/directory/. txt”), and textFile(“/my/directory/.
How do I read a PySpark file?
How To Read CSV File Using Python PySpark
from pyspark.sql import SparkSession.spark = SparkSession . builder . appName(“how to read csv file”) . spark. version. Out[3]: ! ls data/sample_data.csv. data/sample_data.csv.df = spark. read. csv(‘data/sample_data.csv’)type(df) Out[7]: df. show(5) In [10]: df = spark.
Can Spark write to S3?
Using spark. write. parquet() function we can write Spark DataFrame in Parquet file to Amazon S3. The parquet() function is provided in DataFrameWriter class.
What is Spark SQL?
Spark SQL is a Spark module for structured data processing. It provides a programming abstraction called DataFrames and can also act as a distributed SQL query engine. It enables unmodified Hadoop Hive queries to run up to 100x faster on existing deployments and data.
Can we write Python code in spark?
Introduction. PySpark is a Spark library written in Python to run Python application using Apache Spark capabilities, using PySpark we can run applications parallelly on the distributed cluster (multiple nodes). In other words, PySpark is a Python API for Apache Spark.
How do I use spark code?
Write and run Spark Scala jobs on Dataproc
On this page.Set up a Google Cloud Platform project.Write and compile Scala code locally. Use Scala. Create a jar. Copy jar to Cloud Storage.Submit jar to a Dataproc Spark job.Write and run Spark Scala code using the cluster’s spark-shell REPL.Running Pre-Installed Example code.
How does spark Read RDD?
1. Spark read text file into RDD
1.1 textFile() – Read text file into RDD. sparkContext. 1.2 wholeTextFiles() – Read text files into RDD of Tuple. sparkContext. 1.3 Reading multiple files at a time. 1.4 Read all text files matching a pattern. 1.5 Read files from multiple directories into single RDD.

