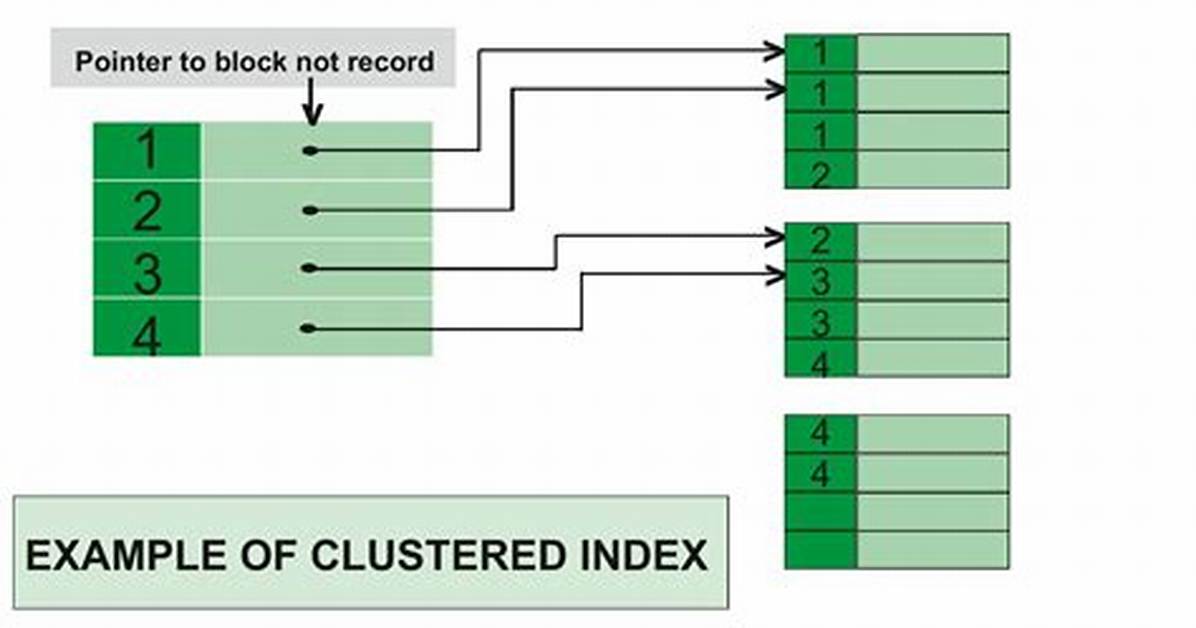
A Clustered index is a type of index in which table records are physically reordered to match the index. A Non-Clustered index is a special type of index in which logical order of index does not match physical stored order of the rows on disk.
What is clustered index with example?
Clustered Index. A clustered index defines the order in which data is physically stored in a table. Table data can be sorted in only way, therefore, there can be only one clustered index per table. In SQL Server, the primary key constraint automatically creates a clustered index on that particular column.
What is the advantage of clustered index?
A clustered index is useful for range queries because the data is logically sorted on the key. You can move a table to another filegroup by recreating the clustered index on a different filegroup. You do not have to drop the table as you would to move a heap.
How do clustered indexes work?
A clustered index alters the way that the rows are physically stored. When you create a clustered index on a column (or a number of columns), the SQL server sorts the table’s rows by that column(s). It is like a dictionary, where all words are sorted in an alphabetical order.
Is primary key clustered index?
A primary key is a unique index that is clustered by default. By default means that when you create a primary key, if the table is not clustered yet, the primary key will be created as a clustered unique index.
What is SQL clustering?
SQL Server clustering is the term used to describe a collection of two or more physical servers (nodes), connected via a LAN, each of which host a SQL server instance and have the same access to shared storage.
Which index is faster in SQL Server?
A clustered index may be the fastest for one SELECT statement but it may not necessarily be correct choice. SQL Server indices are b-trees. A non-clustered index just contains the indexed columns, with the leaf nodes of the b-tree being pointers to the approprate data page.
How do I create a clustered index in SQL?
On the Table Designer menu, click Indexes/Keys. In the Indexes/Keys dialog box, click Add. Select the new index in the Selected Primary/Unique Key or Index text box. In the grid, select Create as Clustered, and choose Yes from the drop-down list to the right of the property.
Where clustered index is stored?
Clustered indexes are stored as trees. With clustered index, the actual data is stored in the leaf nodes. This can speed up getting the data when a lookup is performed on the index.
When should we use clustered index?
Since, non-clustered indexes are stored at a separate location than the original table, non-clustered indexes consume additional disk space. If disk space is a problem, use a clustered index.
Can we create clustered index without primary key?
Can I create Clustered index without Primary key? Yes, you can create. The main criteria is that the column values should be unique and not null. Indexing improves the performance in case of huge data and has to be mandatory for quick retrieval of data.
Can clustered index have null value?
For the clustered index, the column doesn’t need to be unique and/or without null. A column with duplicates and null values is fine for creating a clustered index. For a foreign key, it must reference a column with a unique index on it but not necessarily a primary key or without null value.
Can clustered index have multiple columns?
Short: Although SQL Server allows us to add up to 16 columns to the clustered index key, with maximum key size of 900 bytes, the typical clustered index key is much smaller than what is allowed, with as few columns as possible.
Does clustered index need to be unique?
SQL Server does not require a clustered index to be unique, but yet it must have some means of uniquely identifying every row. That’s why, for non-unique clustered indexes, SQL Server adds to every duplicate instance of a clustering key value a 4-byte integer value called a uniqueifier.
How does index work in SQL?
Indexing is a way of sorting a number of records on multiple fields. Creating an index on a field in a table creates another data structure which holds the field value, and a pointer to the record it relates to. This index structure is then sorted, allowing Binary Searches to be performed on it.
Should all tables have a clustered index?
Yes, every table should have a clustered index. The clustered index sets the physical order of data in a table. You can compare this to the ordering of music at a store, by bands name and or Yellow pages ordered by a last name.
How do you choose a clustered index?
What are the options for a clustered index?
Option 1 – create an “id” column that is either an int or bigint and is also an “identity” Options 2 – Use a unique natural key made up of one or more columns. Option 3 – Use a non-unique natural key. Key width. Non-unique keys / uniqueifier’s.
What is the difference between primary and clustering index?
Primary key is unique identifier for record. It’s responsible for unique value of this field. It’s simply existing or specially created field or group of fields that uniquely identifies row. And clustered index is data structure that improves speed of data retrieval operations through an access of ordered records.

