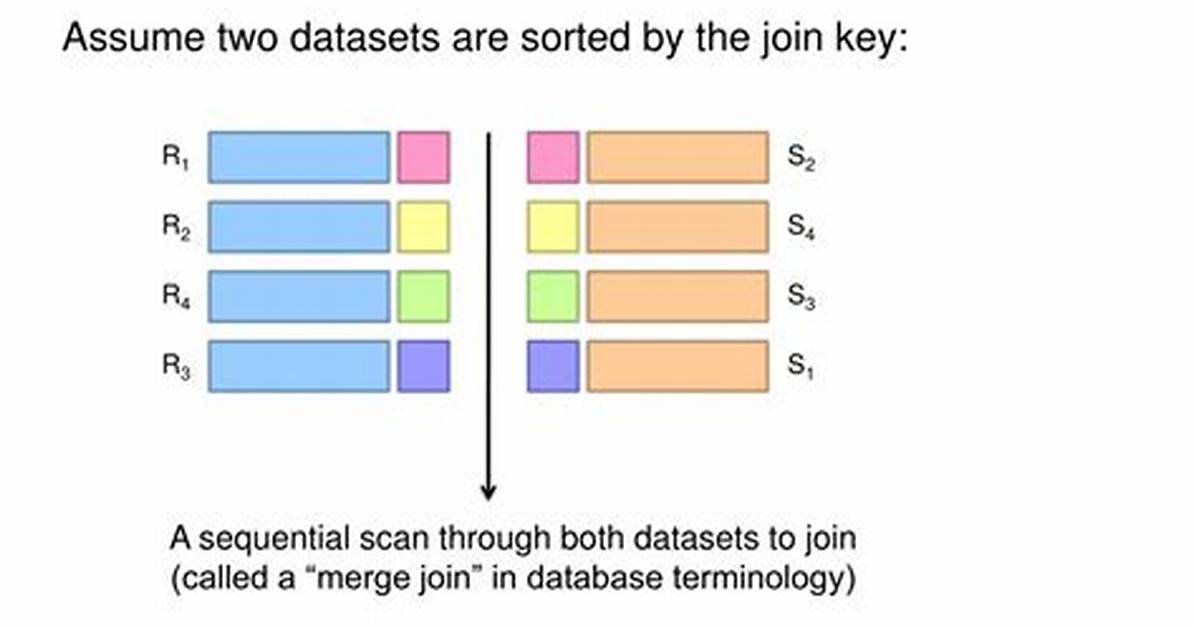
Map join is a Hive feature that is used to speed up Hive queries. It lets a table to be loaded into memory so that a join could be performed within a mapper without using a Map/Reduce step. … Map join is a type of join where a smaller table is loaded in memory and the join is done in the map phase of the MapReduce job.
What is map side join in MapReduce?
Map-side join – When the join is performed by the mapper, it is called as map-side join. In this type, the join is performed before data is actually consumed by the map function. It is mandatory that the input to each map is in the form of a partition and is in sorted order.
What are the common problems with map side join?
The most common problem with map-side joins is lack of the avaialble map slots since map-side joins require a lot of mappers. The most common problems with map-side joins are out of memory exceptions on slave nodes. The most common problem with map-side join is not clearly specifying primary index in the join.

