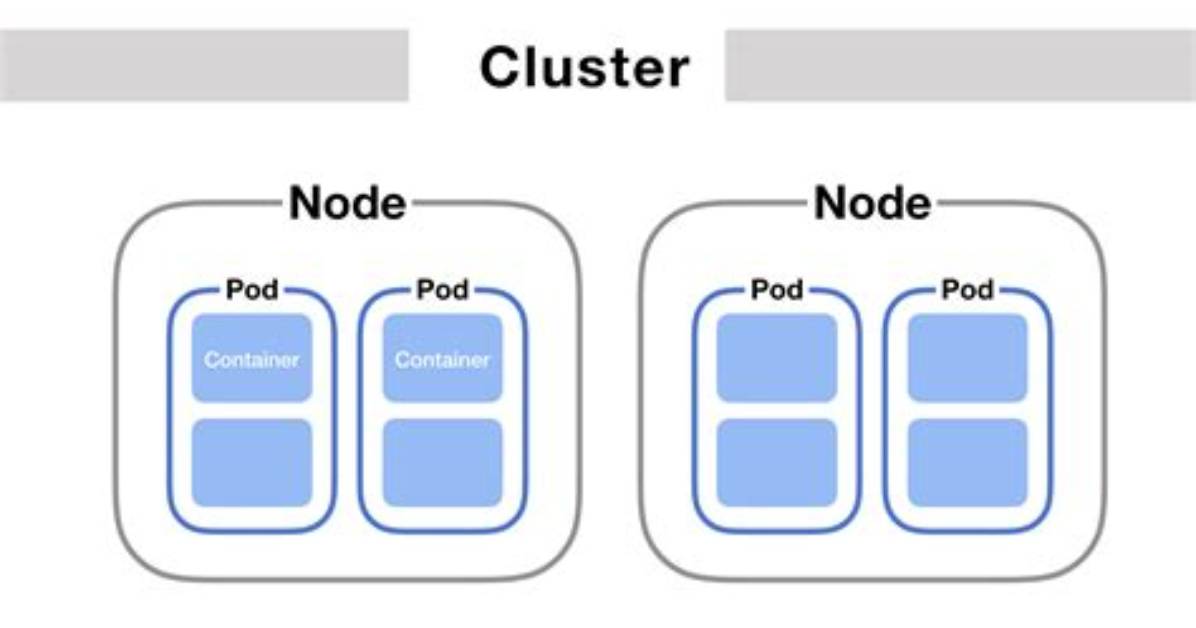
A cluster is a pool of similar workers running under a parent Node process. Workers are spawned using the fork() method of the child_processes module. This means workers can share server handles and use IPC (Inter-process communication) to communicate with the parent Node process.
What is a cluster vs node?
In Hadoop distributed system, Node is a single system which is responsible to store and process data. Whereas Cluster is a collection of multiple nodes which communicates with each other to perform set of operation. Multiple nodes are configured to perform a set of operations we call it Cluster.
What is 2 node cluster?
2 node failover cluster is a failover cluster which has two clustered node servers. Refer to following articles to understand failover cluster and how to configure a failover cluster: Failover Cluster Step-by-Step Guide: Configuring a Two-Node File Server Failover Cluster.

